#translation

37 notes

588,000 Audio Clips and Counting

2026-07-09 · 4 min read

LangQuest just crossed 588,000 community-contributed audio clips. I checked the number twice before writing it down, partly out of habit and partly because of the dashboard incident below.

The largest single language in the set is past 230,000 clips on its own. Everything else is a long tail—dozens of languages, most with a few hundred to a few thousand clips, contributed by people recording in the language they actually speak, not a language a data vendor decided was worth paying for.

That long tail is the point. Some of the languages sitting in LangQuest right now have zero presence in any existing AI model. Not “underrepresented”—absent. There’s data in LangQuest already that isn’t even in AI models—languages that have never been done before. This isn’t just fuel for another translation feature; it’s the first entry in the ledger for languages that currently don’t have one.

Worth saying plainly: even the unlabeled audio counts. A clip nobody’s transcribed yet still tells you what a language sounds like—its phoneme inventory, its prosody, its rhythm. For languages with this little existing data, corpus value doesn’t wait on annotation. Every recording is evidence a model could eventually learn from, transcribed or not.

Now the part that taught us something. For a while, LangQuest’s internal dashboard had a “most common language” widget, and it confidently reported “English” as our top language. This was wrong on its face—English is, structurally, the least interesting language in this dataset—but it took embarrassingly long to notice, because the number next to it looked plausible enough not to question.

The cause, though, wasn’t a query bug. The widget was reading the project title, and a lot of those titles had a language name typed straight into them—“English,” over and over. That wasn’t boilerplate; it was contributors who didn’t yet know what the language dropdowns were for, so they wrote the target language into the project name instead. The dropdown that should have carried the real language often sat untouched. The widget wasn’t misreading the data so much as faithfully reporting what people had typed—and what they’d typed was a signal about our onboarding, not about the audio.

Nothing was lost, and nothing here is even fixed yet. No clips were mislabeled at the source, and you can still pull up the project-title breakdown to see exactly what the data comprises. But there’s no one-line query change that makes this go away—it’s a UI problem, and the real fix is upstream: people need to understand what those dropdowns mean before they name a project. The takeaway wasn’t “patch the widget,” it was “we need better onboarding.” Still, it’s a good reminder that a dashboard is itself a claim about your data—here, quietly, a claim about our interface—and claims deserve the same skepticism whether they come from a model or from your own UI. I trust the 588,000 number because I went and checked it against the raw table, not the widget.

More on the data-scarcity problem this is meant to chip away at soon.
Permalink →

In a room of around forty consultants, one I respect raised five objections to “AI in Bible translation” in the space of about ten minutes: it can’t use the Greek and Hebrew, it has no dictionary, it doesn’t know genre, you can’t give it a translator’s prompt, and you can’t feed it small, controllable batches of text. Every one of those is a fair complaint. None of them is about the tool we’re actually using.

They’re objections to Google Translate.

Seq2seq machine translation—the architecture behind Google Translate and its era-mates—really did work that way. It mapped strings to strings with no access to source-language grammar as an object you could reason about, no lexical resources beyond whatever got baked into training, no sense of genre or register beyond statistical correlation, and no mechanism for a human to say “translate this the way we discussed last week” and have it stick. If that’s the AI you have in mind, the objections aren’t just fair, they’re the whole story. I’ve spent enough time watching seq2seq output wander off-register mid-sentence to know the scar tissue is earned.

But a modern LLM can read the Hebrew, hold a conversation about a difficult word’s semantic range, look up a lexicon entry you hand it in context, take a translator’s brief as a literal system prompt, and work in exactly the batch size a team wants—a verse, a paragraph, a pericope. It can be shown the genre and asked to translate accordingly. None of this is hypothetical; it’s the ordinary operating mode of the tools I use most weeks. So when I hear the same five objections raised against “AI,” I want to redirect: every objection I hear to “AI in Bible translation” is actually an objection to Google Translate. Which means the objection is sound, but the target has moved.

I don’t think this makes the skepticism illegitimate. Consultants built their caution around real failure modes, over years of watching tools get chosen from the top down and pushed into low-resource languages even after the field had already seen them produce fluent-sounding nonsense. That caution is a feature of the field, not a bug to route around. The useful move isn’t to say “you’re wrong, AI is great now”—it’s to ask which specific objection still holds against a system that can read source text, hold a controllable-length conversation, and be handed a prompt like any other collaborator. Some of them, updated for the new architecture, still land. Most of the five I listed above don’t survive contact with what an LLM can actually do, though—which is a separate question from whether the output is good, a question I’ve tried to be more precise about before.

That precision question is where I get more cautious, not less. There’s a pull toward settling all of this with a rigorous benchmark—controlled comparison, blinded reviewers, speed and quality scored against a fixed rubric. I understand the appeal; it’s the responsible-sounding thing to do. But I’ve come to distrust it for a specific reason: by the time you finish the rigorous benchmark, the thing you benchmarked is obsolete. The workflow, the model, the prompting approach—all of it will have shifted meaningfully in the months a careful study takes to design, run, and write up. What you publish is a precise measurement of a tool nobody is using anymore, dressed up in the authority of a number. I’d rather have a translator’s rough, unrigorous sense of “this draft used to take me a day and a half, now it takes an afternoon” than a beautifully controlled study of last year’s pipeline. It’s less defensible on paper and more true in practice—false precision is still false.

That same instinct toward “faster at what, exactly” applies to the bigger debate hovering over all of this: is AI-assisted translation faster than the traditional process? I’ve started to think that’s the wrong question, or at least an underspecified one. Traditional translation and AI-assisted translation quite often aren’t racing toward the same finish line. A team producing a digital-only translation for a community that needs Scripture in an app this year has a different goal than a team producing a fully checked, print-ready Bible meant to anchor a language’s translation for a generation. Comparing their speed head-to-head is a bit like timing a sprinter against a marathoner and declaring one of them slow. “Is AI faster than traditional translation?” is the wrong question. Faster at what—and toward whose goal? This is the same move I made in thinking through Occam’s razor and translation: the interesting question usually isn’t which process is objectively better, it’s what inputs and outputs a given goal actually requires, and whether the process in front of you is shaped for that goal or just inherited from a different one.

I don’t think any of this settles the underlying argument about whether AI belongs in Bible translation workflows at all—that’s a longer conversation, and a more contested one than I’m trying to resolve here. But I’d like the argument to be about the tool that’s actually in the room. Google Translate earned its objections. The thing translators are using now is a different animal, and it deserves to be evaluated as one—carefully, skeptically, and on its own terms, rather than refuted by proxy.

Permalink →

Every demo I give starts with the same reflex from the audience: they want to see the model translate a hard verse well. That’s the “sparkle button” moment, and I used to think it was the whole pitch. Increasingly I don’t. A lot of the friction in a real translation project has nothing to do with translation quality at all — it’s project management. Who’s done Genesis. Who’s approved Exodus. Which reviewer has the current draft of Leviticus, and has anyone told them Numbers is ready. If we can point AI at that, it’s arguably more valuable than a better draft of any single verse, because it’s friction every project pays regardless of how good the translation itself is.

I don’t have a rigorous number for how large that share is, so I want to be careful here rather than confident. The figure I keep coming back to — heard from Reinier, who built Paratext, the software most of the field’s translation project management already runs on — puts project-management overhead at somewhere around 36% of total translation friction. I’m citing that because it matches everything I’ve seen firsthand, not because I’ve independently audited it, and I’d rather flag that than dress up a remembered conversation as a verified statistic.

Whatever the precise number, the shape of the claim matches what I’d expect from watching real projects. Translators lose time to status-chasing, handoff ambiguity, and duplicate work far more than they lose time to a model producing a mediocre first draft — a bad draft gets fixed in minutes; a lost handoff can stall a book for weeks. If that’s roughly right, it reframes where the leverage is. The sparkle button is a nice demo. The unglamorous version — an agent that knows who has what, what’s blocking what, and what needs a nudge — is the one that actually compounds across a whole Bible.

I have one real data point that makes this concrete rather than theoretical, and I want to present it more conservatively than the raw comparison suggests, because the comparison is easy to oversell. A team of two translators completed a full Bible translation in about a year. Sagamore Institute’s September 2022 report, A Study of Cost and Use of Funds in Bible Translation — commissioned by the Maclellan Foundation for illuminNations Resource Partners, based on self-reported data validated against audited financials — put the field average at roughly 15.8 years and $937,446 per complete Bible.

Even being conservative about it, that’s something like two, three, or four times faster than the field average, not fifteen times faster, and I think the smaller number is the honest one. The comparison isn’t apples to apples in several ways that matter: this was a high-resource language with existing reference translations to draw on, the two translators were already professionals, and “done” here means digital-ready, not print-ready — print typically adds another one and a half to two and a half years of typesetting, formatting, and final checks on top. A fifteen-year average almost certainly includes projects in far lower-resource languages, with far less existing scaffolding, and I don’t want to imply this team solved a problem that’s actually much harder in most of the places Bible translation happens.

What I do think the comparison shows is that the acceleration is real and worth taking seriously, even after you strip out every favorable condition you can find. And notably, neither of the two speed levers here — the model’s draft quality, or the reduced project-management overhead — did all the work alone. The team wasn’t just generating faster; per the pattern I described in Steering, Not Batch-and-Correct, they were correcting in context, which is itself a project-management behavior as much as a translation one — it’s about how work flows from one verse to the next, not just how good any single prediction is. I’d guess if I could actually decompose their year into “time saved on drafting” versus “time saved on not losing track of where things stood,” the second number would surprise people who assume this is purely a model-quality story.

None of this is a claim that Bible translation project management is a solved problem, or that 36% (or any other number) is the right way to carve it up. It’s more that I keep being drawn back to the boring part of the workflow as the place with the most unclaimed leverage, in a field where everyone — myself included, most days — wants to talk about the model instead.

Permalink →

Steering, Not Batch-and-Correct

2026-07-08 · 6 min read

I’ve started thinking about AI-assisted translation the way I think about flying a plane. Not takeoff and landing — the boring middle part, where the whole job is thousands of tiny course corrections. A pilot doesn’t fly a thousand miles off heading and then swing back. They nudge, constantly, and each nudge changes the trajectory for everything that follows. That’s steering. The alternative — fly wherever the plane happens to go, then fix the path after landing — isn’t really an alternative, it’s a category error. But it’s more or less how most people still do AI-assisted translation: generate a draft, then post-edit it.

The generate-then-fix pattern is everywhere in machine translation tooling, and for good reason — it’s simple, it maps onto existing editorial workflows, and for a lot of content it’s fine. But I’ve become convinced it’s the wrong default for anything that depends on in-context learning, which is most of what I work on. Here’s the distinction I keep coming back to: when you correct a translation in context, before the model has moved on, that correction becomes part of the context for every subsequent prediction. When you batch-generate first and correct afterward, the correction lands in a document, not in the model’s working context for the next verse. It’s informative to a human reviewer. It’s close to invisible to the model.

Concretely: imagine you finish Genesis 1:1, and you corrected three things — a term choice, a syntactic pattern, an idiom. Am I gonna have to correct those same three things in every other verse where they show up? That would be crazy. If the correction is made in-context and the model sees it before generating Genesis 1:2, it doesn’t have to be. If it’s made afterward, in a separate editing pass, it does — you’ll be fixing the same idiom for the two-hundredth time in Deuteronomy, wondering why the model “isn’t learning.” It isn’t that the model can’t learn. It’s that batch editing never gave it the chance.

Whether this matters depends a lot on the stakes. For low-stakes content — app UI copy, a button label, something a user skims and moves past — generate-and-fix is genuinely fine. Nobody’s faith or family history hinges on a “Submit” button. But for high-trust, educational, or scriptural content, the calculus flips, because a fluent wrong answer is a different kind of failure than an obviously bad one. A garbled, clunky translation gets caught — it looks wrong, so someone checks it. A confidently fluent wrong translation doesn’t announce itself; it reads naturally and gets trusted. I’ve come to think a confident wrong answer is worse than no answer at all, and steering is partly a response to that asymmetry: it’s a way of keeping a human correction in the loop before fluency gets a chance to disguise an error, rather than trying to audit fluency after the fact. This is the same instinct behind treating translation quality as something that has to be actively converged on rather than assumed — I wrote about the social, consensus-driven version of that idea in Consensus Translation.

I have a real case that convinced me this isn’t just theory. On a full Bible translation project in Portuguese, we saw both patterns play out on the same underlying system. One workflow involved continuous correction — a translator reviewing and correcting essentially every prediction as it was generated, feeding straight back into the next one. Another workflow, used by some translators on the same team, was to batch-draft a chunk of verses first and edit them afterward, document-style. The batch-and-edit group came away convinced the AI wasn’t learning from their corrections — the same errors kept resurfacing chapter after chapter. But the model wasn’t failing to learn; it was never shown the correction at a moment when it could use it. It’s like flying a thousand miles and then trying to correct it, instead of correcting as you go — the destination doesn’t move just because you finally noticed you were off heading.

That case study is what pushed me toward a rougher framework I’ve been using since, mostly as a sequencing heuristic rather than anything rigorous: golden path and silver path. Golden path is for when someone’s actually watching — a human reviewing and correcting every single prediction in real time. Because that attention is expensive, you spend it on the material most worth learning from: the most distinctive, highest-coverage constructions, the ones whose corrections will generalize furthest downstream, translated first. Silver path is for when nobody’s watching as closely — the model runs ahead on material that’s comparatively easy or low-risk, and anything that looks uncertain gets flagged for a human to review later rather than corrected live. Golden path when someone’s watching, silver path when they’re not.

I don’t think this framework is settled — it’s closer to a rule of thumb I’ve been testing against real projects than a methodology I’d defend in the abstract, and I’d guess the boundary between “distinctive enough to deserve golden-path attention” and “safe enough for silver path” needs to get a lot more precise before this generalizes past the projects I’ve watched it work on. But it’s already changed how I sequence work, in the same spirit as the simplification argument in Occam’s Razor and Bible Translation: before adding more review infrastructure, ask whether the correction you’re about to make is actually reaching the next prediction, or just the next document.

Permalink →

I ran into something last week that unsettled me more than expected. I was testing whether a model could translate a passage using only its own reasoning, so I hid the source text behind a simple substitution cipher before handing it over — the idea being that if the model could still produce a faithful translation, it would have to be doing something closer to genuine cross-lingual reasoning than pattern completion. It decrypted the cipher and recited the verse anyway. Correctly. Immediately. The Bible is so memorized by frontier models that hiding the source text doesn’t work — the model just decrypts and recites it anyway.

That’s stranger than it first sounds. This wasn’t a model translating an encrypted string. It was a model recognizing that a scrambled string of characters was shaped like a passage it already had memorized verbatim, discarding the cipher as a distraction, and reciting from memory. That’s a different capability than translation, and it means a huge chunk of what looks like “the model translated this well” for biblical text is really “the model already knew this text in every language I asked for.” You can’t use Scripture to test whether a model can translate, because for Scripture specifically, the model usually doesn’t need to.

This is a genuine methodological problem, not just a fun fact. If I want to evaluate — or train — a system’s ability to reason from meaning to meaning rather than reciting a memorized target string, I need source material the model hasn’t swallowed whole. Obfuscating the surface form doesn’t work, as I just found out the hard way. What might actually work is changing what the “source” is in the first place.

Acting the scene instead of laundering the words

There’s a practice-level version of this same insight that I’ve been leaning on for a while, mostly with human translators and increasingly as an instruction to models: stop translating the words. Act the scene. Then say what just happened in your own language.

The reasoning is the same as in prioritizing semantics over structures: a word is not a translation unit, it’s a residue left behind by a meaning that already happened. Translating the residue is really just copying with extra steps — the failure mode the cipher experiment exposed at scale. A model (or a person) staring at a string of tokens finds the shortest path to an output resembling those tokens, and if it’s already memorized the “right answer,” the shortest path is recall, not comprehension. Acting the scene forces a detour around that shortcut. You have to know who is speaking, to whom, what they want, what’s at stake, before you’re allowed to say anything at all. Only then do you say what happened, in whatever language you’re working in.

The more rigorous version: don’t feed it the words at all

The practice-level fix is good discipline, but discipline is not architecture, and I’d rather not depend on a model or a translator “resisting the urge” to recall a memorized string. The more rigorous fix, and the one I actually want to build, is to stop handing the model literal source text as the thing to be translated at all.

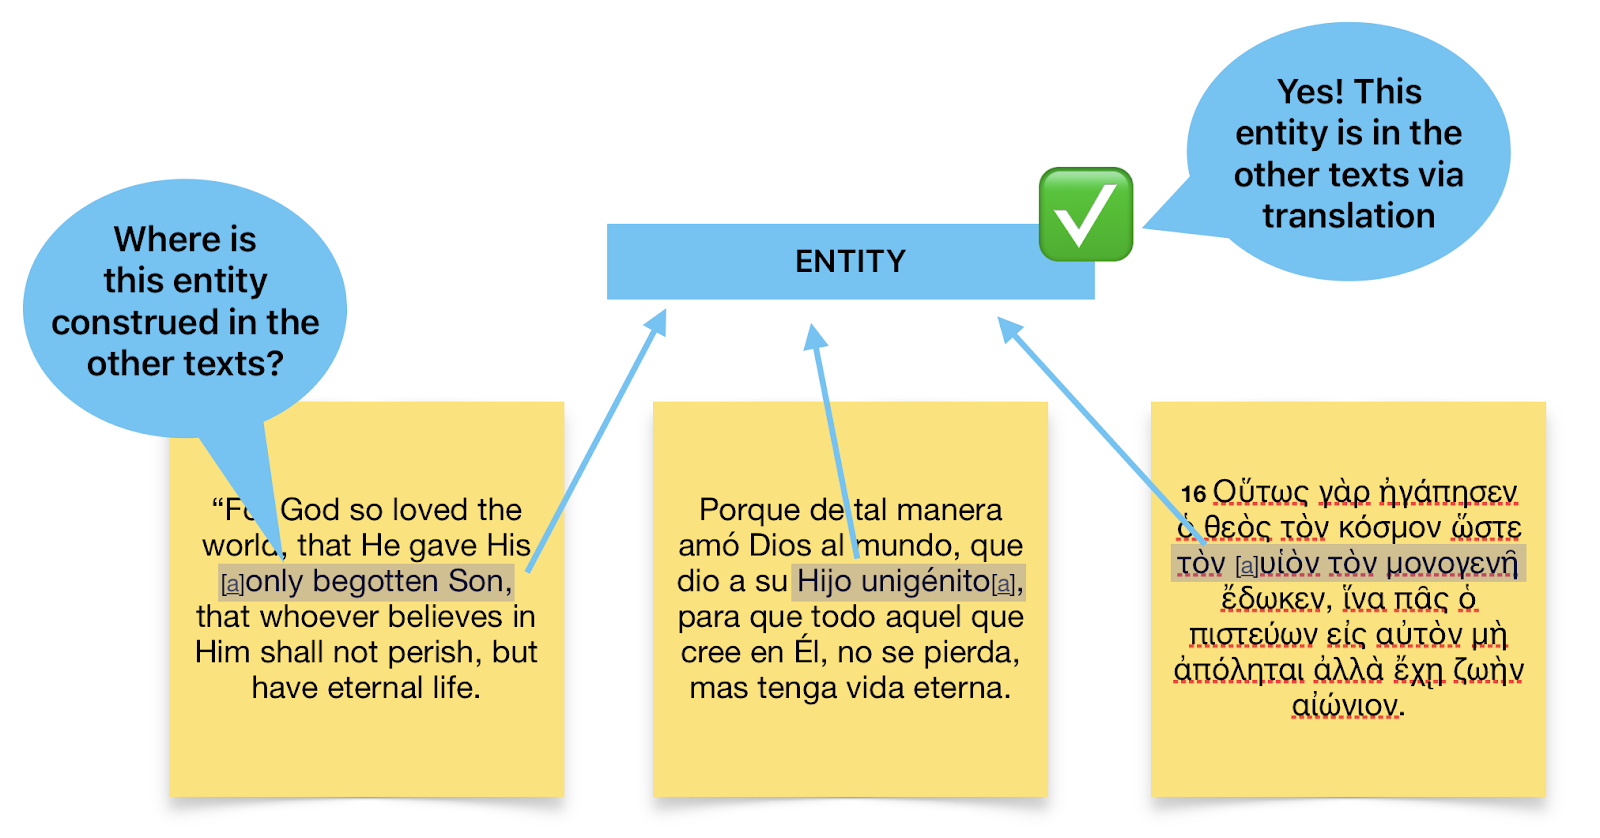
Instead, represent the passage as a language-agnostic semantic description: pericopes broken down into nested units of who is speaking, to whom, and what is being communicated — speech acts nested inside speech acts, the way narrative and dialogue actually nest inside each other. This is the same move I described in the case for dynamic equivalence alignments — form → meaning → form instead of form → form — pushed one step further upstream. Instead of asking a model to align a translation back to source words after the fact, you never give it the source words as the object to reproduce in the first place. Its job becomes representing the meaning of a discourse unit faithfully, not pattern-matching against a corpus it already has memorized down to the verse numbers. If there’s no recognizable surface string to recite, “recite the memorized answer” stops being a viable shortcut, and the model actually has to do the thing you’re asking it to do. This is really an extension of the point I made in beyond word alignments: the word was never the right unit, and now I have a concrete reason — memorization contamination — to stop treating it as one even operationally.

Where this is honestly still rough

I don’t want to oversell this, because I’ve already tried a related methodology and it only sort of worked. I built a multimodal process I’ve been calling Familiarize → Internalize → Articulate — acting out a passage, drawing the scene, studying the characters and key terms — before ever producing a rendering, as a more embodied version of the “act the scene” instinct above. In practice it can shunt between layers of context in ways that are only sometimes helpful; moving between acting, drawing, and terminology study doesn’t reliably converge on a clearer semantic representation, it sometimes just adds noise. And the supporting resources for it — the character studies, the term glossaries, the scaffolding that’s supposed to make internalization tractable rather than vibes-based — are still unfinished.

So this isn’t a solved problem, it’s a diagnosis with a promising direction attached. The cipher experiment told me the failure mode is real and larger than I assumed. The semantic-description architecture is my best current guess at a fix that doesn’t rely on willpower. Whether nested speaker/addressee/content units are actually the right granularity, and whether a model can be made to represent meaning at that level reliably, is still very much open.

Permalink →

Authorization Is Local

2026-07-01 · 5 min read

I’ve been sitting with a discomfort for a while now: our tools are getting faster than our trust can keep up with. That’s not a complaint about the tools — the models are good, genuinely good, at drafting translations, catching inconsistencies, surfacing alternate renderings. The discomfort is about what happens after the draft exists.

When I’m validating code, the bar is low and the feedback loop is fast. You try it out and see if it works. Tests pass or they don’t. A function either returns the right value or it doesn’t, and if it doesn’t, you fix it and try again in about the time it takes to hit save. Nobody has to trust me personally for the code to be correct — the correctness is baked into whether it runs.

Scripture translation doesn’t work that way, and I don’t think it ever will, no matter how good the models get. There’s no compiler for “is this the right way to render this passage for this community.” The validation is person-centric: it runs through relationships, history, and standing in a community, not through a test suite. You can’t leave people behind in the process, because otherwise who are you making it for?

That’s the sentence I keep coming back to. It’s easy, when you’re excited about a pipeline that can produce a full draft translation of a book of the Bible in an afternoon, to start treating the humans in the loop as a bottleneck to be optimized away. But the humans aren’t a bottleneck to the goal. In this domain, they basically are the goal, or at least they’re inseparable from it.

Which gets at something I’d call the authorization thesis: content doesn’t become usable — doesn’t become trusted — until a responsible party signs their name to it. Not “signs” in a legal, contractual sense, necessarily. Signs in the sense of standing behind it, in public, with their own reputation. Until that happens, no amount of translation accuracy matters, because accuracy was never the thing being evaluated.

Put more bluntly: if I just generate a whole Bible, I can do that — but nobody trusts it, nobody cares. I mean that fairly literally; I could kick off a pipeline tonight and have a full draft by morning. It would be fluent, mostly accurate, and worth approximately nothing to the community it’s supposedly for, because nobody with standing in that community said “yes, this is ours, I stand behind it.” Without that, it isn’t scripture yet. It’s AI slop with good grammar, and everyone downstream can smell the difference even if they can’t articulate it. I’ve written before about why I think Bible texts should carry no restrictions at all — but licensing freedom and trust turn out to be different axes entirely. You can be free to use a text and still not trust it. Openness solves distribution; it doesn’t solve authorization.

So who does the signing? This is the part that resists every instinct I have as someone who builds software, which is to find the general solution and encode it once. There isn’t one, and I’ve stopped expecting to find one. Who’s allowed to approve a Bible translation? In one place, the bishop. In another, the king. I’ve talked with people doing this work in Nigeria where the actual sign-off runs through a king or a local chief — not a denominational structure at all, but a traditional authority that predates any mission agency’s org chart. Elsewhere it’s a church-planting network’s leadership team. Elsewhere it’s a single respected local pastor whose word is sufficient because of decades of relationship, not because of any title. Elsewhere it’s a denomination’s formal review process, with committees and sign-off sheets.

None of these map onto each other, and I don’t think you can build a workflow engine that abstracts over all of them without doing violence to the thing that makes each one legitimate in its own place. That’s not a gap in the tooling waiting to be filled by a smarter permissions system — it’s the actual shape of the problem. Authorization is local. It’s socially embedded in ways that resist standardization, the same way permissionless, community-driven translation resists centralized oversight from agencies who assume they know best from a distance.

The tools can get faster. The drafts can get better. But the question of who gets to say “this is trustworthy” was never a technical question, and I don’t think generating more text, faster, gets us any closer to answering it. If anything, it raises the stakes on getting the answer right, because the bottleneck was never production. It’s figuring out, community by community, whose name actually carries weight — and building tools patient enough to wait for that name before calling anything finished.

Permalink →

#translation #nlp #machine-learning

Machine translation for languages with limited resources is a difficult challenge. Here’s a straightforward pipeline that could yield some interesting results:

  1. Accuracy First: Start with an interlinear-like, literalistic rendering. This step uses statistical glossing or high-granularity predictions to create a word-for-word translation. It’s not pretty, but it’s “accurate” in the sense that it is a representation of the source text.

  2. Naturalness Post-Edit: Here’s where it gets interesting. Take your literal translation and try to iteratively make it sound natural:

    • Gather as much unstructured text in the target language as you can.
    • Measure the likelihood of your output from step 1 using different slices of this data (think sliding window n-grams or similar techniques). (This is kind of like measuring perplexity of a model.)
    • Systematically swap and rearrange parts of the translation.
    • Rank the different versions based on their ‘naturalness’ (as defined by the likelihood measurements).

This approach seems deceptively simple, but it could be quite promising. By separating the accuracy and naturalness concerns, we’re able to leverage the strengths of both statistical and corpus-based methods.

The beauty of this pipeline is its potential to work with limited resources. Even if we don’t have parallel corpora (expensive to get), or extensive training data (requires model fine-tuning, quickly gets out of date, and likely will be inaccurate until some critical mass of data is reached), we can still produce a reasonable translation by focusing first on word-level accuracy and then on phrase-level naturalness.

You could also add additional steps to the pipeline, such as:

  • Back-Translation: Translate the output of the previous step (now in the target language) back to the source language for comparison.
  • Gloss at Lower Granularity: Use the output from the previous step and attempt to re-gloss the text at a lower granularity (e.g., complete phrases).

Of course, there are challenges to consider. I suspect such an approach would work best for languages that are similar to the source language, perhaps from the same language family. The potential here lies in the use of more traditional, statistical approaches to machine translation, which are typically much faster and can be iterated many times with minimal resources and more easily measured for success.

Permalink →

#translation

Problem

One of the major hurdles to the translation of the Bible is the assumption that one cannot translate the Bible by paying attention to the language alone. This assumption, whether explicit or implicit, results in Bible translation progressing very slowly, while the translation of other texts can be accomplished in very little time. For example, secular texts are often translated quickly and efficiently because the focus is solely on linguistic accuracy.

Why do we assume that the translation of the Bible must be different from the translation of other texts? There are various reasons that come to mind:

  1. The Bible is a sacred text with a unique status in many cultures.
  2. The Bible is a complex text with a large number of theological concepts and allusions.
  3. The Bible is a historical text with a large number of historical references.
  4. The Bible is a literary text with a large number of literary devices and allusions.
  5. Many Bible translation stakeholders justify their doctrinal claims by appealing to the language of the Bible, raising the stakes of translation to encompass the correct representation of a given group’s doctrinal claims, and not simply the linguistic accuracy of the text.

The result is that the translation of the Bible is often seen as a task that is separate from the translation of other texts, and that it requires a different approach. We are correspondingly slow to translate the Bible, while the translation of other texts can be accomplished in very little time.

Solution

The solution to this problem is to translate the Bible by paying attention to the language alone in its context of production. This task does require comprehension and knowledge of the source text cultural context. However, by restricting the scope of “accuracy” to the language alone, we can sidestep the myriad hurdles and impediments that have been built up around the translation of the Bible.

The main requirement for a Bible translation is not the supernatural, direct guidance of the Holy Spirit, or the direct justification of a given group’s doctrinal claims; the main requirement is to translate the language as accurately as possible. The source text is “theologically accurate,” and so a linguistically accurate translation of that text will also be theologically accurate. This means that by focusing on linguistic precision, translators can ensure that the theological integrity of the Bible is maintained.

Permalink →

#translation

Three months ago, my team was discussing ways to gather translation data for new, undocumented languages that would be helpful for Bible translation, but which sidestepped the intimidation factor that accompanies the prospect of translating the Bible itself.

One idea that came to mind was to create a short novel that would cover the major genres of the Bible in a minimal form.

Here’s an example outline for a short novel that would cover the major genres of the Bible in a minimal form:

Title: “The Sojourner’s Tale”

  1. Prologue: A brief narrative introducing the main character, a sojourner named Elias, and his quest for wisdom and understanding.

  2. Chapter 1: Elias’ journey begins. He encounters a wise old man who shares three proverbs about life, faith, and perseverance.

  3. Chapter 2: Elias arrives in a city where he witnesses a heated argument between two religious leaders. He listens to their debate and reflects on the nature of truth and belief.

  4. Chapter 3: Elias attends a worship service where a liturgical ceremony is performed. The chapter includes a description of the ritual and its significance.

  5. Chapter 4: Elias discovers a letter from his father, which contains a genealogical record of his family and a personal message of love and guidance.

  6. Chapter 5: Elias meets a group of travelers who share a meal with him. During the meal, one of the travelers tells a parable about the importance of compassion and forgiveness.

  7. Chapter 6: Elias has an apocalyptic dream filled with symbolic imagery and prophecies about the future. He struggles to understand its meaning and seeks the advice of a local interpreter.

  8. Chapter 7: Elias encounters a prophet who delivers a message of repentance and hope. The prophet’s words are a mix of poetry and prose, and they deeply impact Elias.

  9. Chapter 8: Elias joins a group of worshippers in singing a hymn of praise. The lyrics of the song are included in the chapter.

  10. Chapter 9: Elias meets a teacher who shares a sermon on the nature of wisdom and the importance of living a righteous life. The sermon includes a short creed or statement of belief.

  11. Chapter 10: Elias faces a moral dilemma and seeks guidance from a trusted mentor. The mentor shares a piece of wisdom literature, similar in style to the book of Ecclesiastes, to help Elias navigate his decision.

  12. Epilogue: Elias reflects on his journey and the lessons he has learned. He pens a letter to his future descendants, sharing his experiences and encouraging them to seek wisdom and live according to the truths he has discovered.

This outline incorporates various genres found in the Bible, including narrative, proverbs, argument, liturgy, genealogy, parable, apocalyptic literature, prophecy, poetry, hymn, sermon, wisdom literature, and epistolary. While condensed, this structure provides a way to showcase the diverse literary forms found in the Bible within a single, cohesive story.

Linguistic levels

While this outline addresses genre coverage, there are also other linguistic levels that we need to consider. These include (among others):

  • Lexical coverage (Biblical key terms, proper nouns, etc.)
  • Semantic coverage (typical domains-specific meanings in the Bible)
  • Interpersonal coverage (typical interpersonal/transactional/political/intertextual/etc. meanings in the Bible)
  • Information structure, logical structure, etc.

One of the ways to make this data particularly useful would be to ensure that contrastive pairs are included in the data at each level. If one wording presents a pair of objects, then another should present only one object but not the other. If one wording realizes a command activity, then another one should realize a request activity using the same lexical items, etc.

In other words, attempting to control the data at each level ensures that the data addresses specific items of interest in translation. However, this is a bit of a double-edged sword, and the wrong way to do this would be to control for formal, grammatical patterns in the source language that are intentionally left behind in translation (cf. Prioritizing Semantics Over Structures).

Conclusion

The outline above lays out an example of how we might approach the task of Bible translation in a new, undocumented language without both the intimidation that normally accompanies the prospect of translating the Bible itself, and also without the security challenges that are implicated in translating the Bible in hostile contexts.

Permalink →

Introduction

The world of Bible translation is on the brink of a paradigm shift. For decades, the process has been centralized, controlled by overseas agencies and individual missionaries. But a new model is emerging—one that’s decentralized, community-driven, and powered by AI.

The Shift Towards Decentralization

This shift towards “permissionless translation at the edge” is not just a possibility; it’s already happening. While many in the Bible translation community are debating how to introduce AI tools, the reality is that people in communities large and small are already running AI models locally on their machines.

Challenges and Opportunities

The traditional paradigm values careful oversight and quality control. It’s understandable, then, that the initial response to AI in translation is often to hit the pause button and implement controls. But this approach risks missing the opportunity that’s unfolding before us.

AI isn’t just a tool to be integrated into existing processes. It’s a catalyst for a fundamental reimagining of how translation happens. It empowers local communities to take ownership of translation, allows for rapid iteration and feedback, and enables translations that are more natural and culturally nuanced.

Enhancing Human Translators

Because AI cannot translate into a language a human has never translated before, the new paradigm doesn’t replace initial human translators—it enhances their capabilities. It turns translation quality into a social process, leveraging community consensus for accuracy. It embraces cultural nuances and local idioms in ways that remote oversight never could.

The Role of Data

The key to unlocking this potential? Data. (See Data is the bottleneck for more on this.) By giving communities tools to document their languages, we provide them with the raw material that AI needs to work. This could lead to rapid transformations in oral-only communities and increased demand for written scriptures.

Embracing the Shift

So, what can we do to embrace this shift?

  1. Recognize that AI in translation isn’t coming—it’s here. We need to engage with it now.
  2. Invest in tools that empower local communities to document their languages and drive their own translation processes.
  3. Shift our focus from control to empowerment. How can we equip communities rather than oversee them?
  4. Prepare for a multi-modal future where text, audio, and visual translations coexist and complement each other.

Conclusion

The future of Bible translation is permissionless, decentralized, and AI-enhanced. It’s a future where every community has the tools to engage with Scripture in their heart language. The question isn’t whether this shift will happen, but how quickly we’ll adapt to it. The revolution in Bible translation is here—are we ready to embrace it?

Last week I presented at the Generating Wisdom Conference at the Museum of the Bible in Washington, D.C. on the topic of “Human Centric AI” and the paradigm shift happening in Bible translation.

An online conference attendee later emailed and summarized the approach described in some of my points with the phrase “Permissionless Translation at the Edge.” I thought this was an excellent summary of the approach, so I’m using it as the title of this post (thanks Greg Outlaw!).

Permalink →

#ai #translation

I’m excited about the potential of OpenAI’s new GPT-4o mini for our Translator’s Copilot project! Here’s why:

Cost-Efficiency

It’s more than 60% cheaper than GPT-3.5 Turbo. This change means zero-drafting with AI can be faster and cheaper.

Improved Capabilities

  • Better handling of non-English text like the larger 4o model (which we have been using extensively)
  • Outperforms GPT-3.5 Turbo on various benchmarks
  • 128K token context window (entire chapters at once!)
  • Multimodal support (future audio possibilities?)

Real-Time Interaction

Low latency could enable faster, more fluid workflows for our translators.

Integration Potential

Strong function calling performance could help us integrate external resources like concordances more seamlessly.

Cautious Optimism

While exciting, we need to approach implementation carefully. Bible translation requires nuance and cultural sensitivity.

Next Steps

  1. Testing on biblical texts in low-resource languages
  2. Refine prompts for smaller model if needed
  3. Plan integration into our existing workflow for Codex
  4. Analyze costs vs. potential improvements

GPT-4o mini could accelerate our mission to make God’s Word accessible to every language community.

What do you think about its potential impact on Bible translation?

Permalink →

#translation #ai

The landscape of Bible translation is rapidly evolving with AI advancements. Our role must shift accordingly. Tech giants are developing powerful translation tools, but they lack one crucial element: data for low-resource languages.

AI’s Potential in Translation

AI can now create accurate, creative Bible translations in major languages within minutes. For low-resource languages, the technology is ready - it just needs data.

Our Unique Contribution

Our mission-driven focus on low-resource languages positions us uniquely to provide the missing piece: language data.

The Real Challenge

The primary obstacle to universal Bible access is no longer translation itself, but gathering sufficient language data for AI translation into each language. Our task is to collect and publish this data in standard, open AI repositories.

A New Direction

To maximize our impact, we must:

  1. Prioritize data collection for low-resource languages
  2. Standardize data formats for AI compatibility (think JSON, not USFM)
  3. Develop user-friendly, offline-first language data collection tools
  4. Streamline our data infrastructure for efficient gathering and sharing (more data, less decisions about data)

The Path Forward

By focusing on our role as data collectors and curators, we can accelerate Bible translation in unprecedented ways. If we dedicate our efforts to data collection now, we’ll enable AI models to translate the Bible into every language faster than ever imagined.

This shift in focus would allow us to leverage our unique strengths and the power of AI, bringing us closer to our goal of making God’s Word accessible to all.

Permalink →

#translation #ai #localization

Please see the following slide deck for a description of the process and potential benefits of using LLMs to generate and localize translator’s notes for the rest of the Bible.

Permalink →

#ai

Comparing languages often requires extensive datasets and complex algorithms. But what if we could gain insights with just a handful of translation pairs? Enter langsim (“language similarity”), an experimental project that aims to do just that.

langsim is a Python library that compares languages using a variety of metrics, even with limited data. From lexical similarity to morphological complexity, it provides a multi-faceted view of language relationships.

Key Features

  • Compares languages using 11 different metrics
  • Works with small datasets (even just a few translation pairs - this is huge for Bible translation into ultra-low resource languages)
  • Language-agnostic approach
  • Easy to install and use

The Road Ahead

It’s important to note that langsim is very much a work in progress. It’s not recommended for production use yet, and there’s plenty of room for improvement. The current metrics are just a starting point, and we’re actively seeking feedback and contributions.

One exciting direction for langsim’s future is leveraging Large Language Models (LLMs) to evolve its language comparison capabilities. Inspired by Stanford’s fascinating DrEureka project, we’re exploring ways to use LLMs to fine-tune the weights of our comparison metrics, potentially leading to more accurate and nuanced language comparisons.

Get Involved

If you’re interested in language comparison, computational linguistics, or just enjoy tinkering with code, we’d love your input. Try out langsim, open issues with your impressions, or contribute to its development.

Let’s push the boundaries of what’s possible in language comparison, one metric at a time!

Permalink →

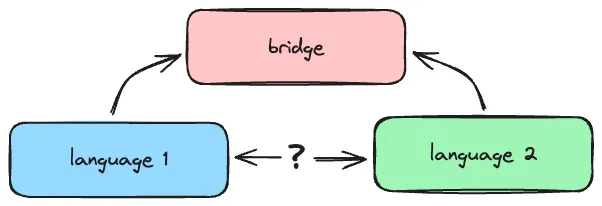
The basic philosophy behind translating between languages is finding a way to bridge the gap.

Bridging the Gap Between Languages

The Established Approach: Understanding and Expert Validation

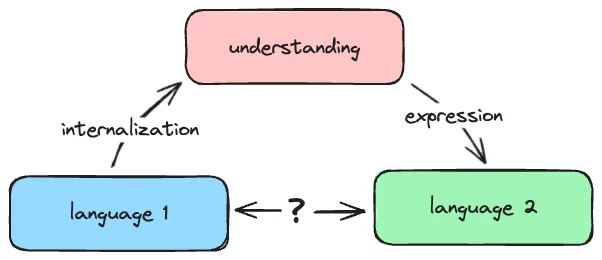
The established approach has been to use an abstract notion of “understanding” as that bridge.

Bridging via Understanding

Under this paradigm, we start with Language 1, internalize and comprehend it to arrive at an “understanding”, and then express that understanding in Language 2. However, validating this approach is challenging, because the interim step of “understanding” does not exist as concrete, discrete units. As a consequence, the approach is not easily scalable, and the internalization process is protracted in an attempt to assure the validity of the “understanding”.

Validity, in turn, is assessed by experts in the target language, the subject matter, and by authorities and gatekeepers from within or without the respective communities.

The New Approach: Multimodal Assets and Consensus Validation

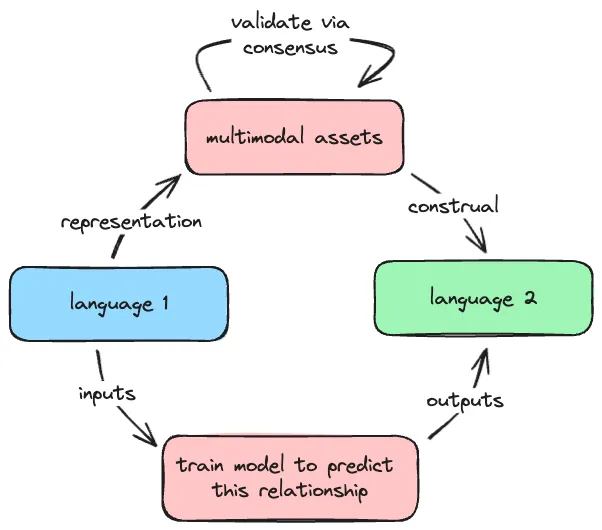
An alternative approach that is easier to validate and scale leverages multimodal assets like images, audio, text, animations, videos, and simulations to serve as the bridge between languages.

Bridging via Multimodal Assets

With this method, Language 1 is represented as a set of multimodal assets. Then Language 2 is generated by interpreting and describing those assets. Validation becomes straightforward, because the mapping between each multimodal asset and its linguistic representation in Language 2 is distinct and unambiguous.

The validation process is simple and proven - present a user with a snippet of Language 2, and ask them to match it to the correct multimodal asset, similar to how a Captcha test works. This allows the approach to be easily scaled without extensive software training.

Once we have established a robust set of validated asset-language pairings for the new language, we can strategically select a subset of the corpus that will provide sufficient data to train a small language model or fine-tune a large language model. As Zhou (2023) demonstrated, a model can be trained to translate the Bible with 90% accuracy using only 3% of the Bible as training data. This suggests that eliciting translations for a carefully chosen subset of a corpus via multimodal assets and Captcha-like validation is feasible.

The key advantage of this approach is that it does not require any prior knowledge of the target language, making it massively scalable for translating low-resource languages that have been historically difficult to support. By focusing data collection efforts on the most information-dense portions of a corpus, we can efficiently gather the necessary training data to enable high-quality machine translation for the long tail of languages.

In summary, using multimodal representations as a bridge between languages offers a promising alternative to the “understanding” based approach that is easier to robustly validate and scale. Combined with strategic subsampling of corpora for data collection, this paradigm shift could dramatically expand our ability to develop machine translation capabilities for low-resource languages.

Reference:

Zhou, Z. (2023). [TBA].

Permalink →

The future of Bible translation increasingly involves the use of crowd-sourcing, Large Language Models (LLMs), and AI to enhance accuracy and efficiency. Here’s how these elements converge to offer a practical solution:

Crowd-sourcing: This approach taps into our only available pool of knowledge for the vast majority of remaining languages, making it possible to translate the Bible into every language. By leveraging the collective wisdom of native speakers - though not necessarily ‘directly’ as translators of the Bible itself, we can ensure that translations are accurate and culturally relevant.

User Interface: Translators interact with simple, customized HTML forms developed by LLMs. These interfaces are intuitive and hide the complexity of the technology beneath, focusing on user needs without added complexity.

Behind the Scenes: Sophisticated seq2seq and open-source agentive models work in tandem with human input. These models augment human translators’ efforts by leveraging input from wherever we can get it. These AI tools augment, improve, and speed up the translation process by generating additional content from what has been provided via crowd-sourcing.

The integration of these technologies is not about flashy innovation but about practical improvements in the translation process. By leveraging these tools, we aim to build an ecosystem that can translate the Bible into every language in the world, made possible by both human and AI-powered machine translation.

Permalink →

Occam's Razor and Bible Translation

2024-05-08 · 3 min read

#translation

Question

Is there a simpler approach to Bible translation?

Tesla’s Application of Occam’s Razor

Tesla faced a massive, patchwork C++ codebase for identifying labelled items in video input for full self-driving. Progress was slow, and scalability for the last 1% of edge cases seemed unattainable.

Then they applied Occam’s razor and shifted to training a model with extensive 360-degree video input and controls output (steering, brake, gas). This approach proved significantly better, improving 5x-10x each month as more video data was uploaded from drivers.

See discussion at 3:42 in this video. Thanks to Birch Champeon for sharing.

Applying Occam’s Razor to Bible Translation

I propose a similar shift in Bible translation.

Currently, we use large legacy apps and newer apps with numerous features and checks. With LLMs and agent-based translation, we can simplify the task.

Starting from first principles: what are the inputs and outputs?

If we move from Greek/Hebrew source texts to a semantic representation, semantics become inputs. A model could then apply these semantics to the collocation and colligation patterns in the target language, possibly by reranking outputs with context awareness.

Like Tesla, we need to crowdsource data to map semantics to target language expressions. One method could involve eliciting translations of semantic units from Greek/Hebrew, displayed in aligned gateway languages familiar to target language speakers.

Synthesizing Crowdsourced Data

However the data is elicited, we need to synthesize crowdsourced data into a coherent whole, i.e., complete, versioned, public domain Bible translations.

Adapting swarm intelligence to Bible translation could be the solution. This would involve numerous agents, each translating small, semantically coherent text units. These translations would be combined and refined by a central agent to ensure consistency and coherence across the translation.

This method would allow a more flexible and scalable translation process, distributing work among numerous agents, each responsible for a manageable portion of the text. This would enable faster, more efficient translation, and greater adaptability to local community needs and preferences.

Every approach has risks and trade-offs, but the prospects of applying Occam’s razor to Bible translation are exciting and promising.

Permalink →

#translation #ai

Vision and Purpose

The Blank Slate Translation Initiative aims to fundamentally reshape Bible translation for the AI age. We envision a future where every community, regardless of size or location, has access to the Bible in their own language.

Our Approach

Our approach leverages emerging AI technologies to empower local communities, potentially reducing translation time and costs dramatically while increasing ownership. Key aspects include:

  1. Iterative process: Continuous improvement through rapid feedback cycles
  2. Decentralized tools: Simple, accessible apps for widespread participation
  3. Crowdsourcing: Enabling all language speakers to contribute
  4. AI integration: Synthesizing diverse inputs into coherent translations
  5. Community-driven: Serving locally-initiated translation projects

Paradigm Shift

By combining AI-powered tools with local expertise, we’re not just enhancing existing methods; we’re exploring new paradigms that could maximize output from minimal input. This strategy positions us to adapt continually to advancing AI capabilities, potentially transforming community-based translation as profoundly as automobiles changed transportation.

Join the Initiative

We invite forward-thinking individuals and organizations to join us in this groundbreaking initiative. Together, we can reimagine Bible translation, ensuring no community is left without access to God’s Word in their heart language.

Permalink →

#translation

This idea was co-ideated with Ben Scholtens

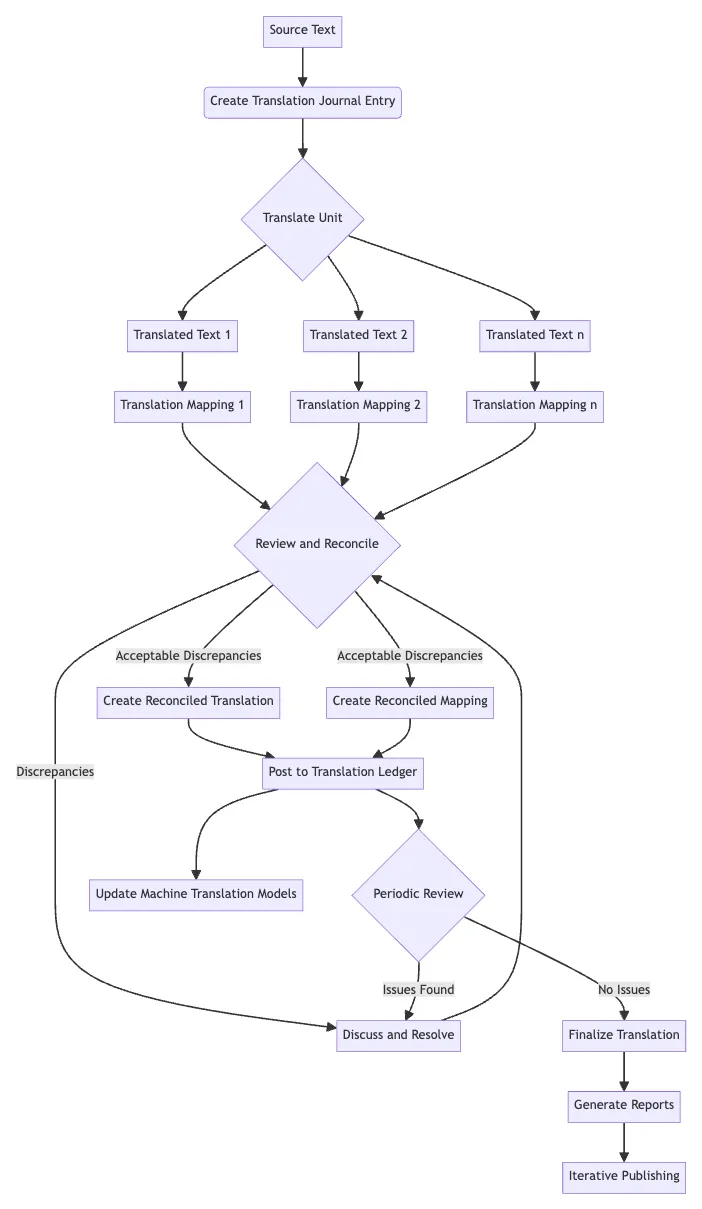
Double-Entry Translation, or Ledger Translation (LT), is a framework that adapts the principles of double-entry bookkeeping to ensure accuracy, consistency, and a clear mapping between the source and target texts in the Bible translation process.

Double-Entry or Ledger Translation Framework

The framework consists of the following components:

  1. Translation Accounts:

    • Source Text (ST): The original text, treated as an asset.
    • Translated Text (TT): The new translation, treated as a liability.
    • Translation Mapping (TM): The mapping between ST and TT, representing the transactions or “translation-actions” for translation-units at multiple levels of granularity (e.g., meaning-based alignments, sliding-window ngram alignments, etc.).
  2. Translation Journal: A chronological record of all translation entries, including the source text, multiple translated texts, and their corresponding translation mappings.

  3. Translation Ledger: A collection of “posted” translations and their reconciled mappings, perhaps organized by book, chapter, and verse, representing the accepted translations and alignments.

  4. Translation Process:

    • One or more translators create journal entries for each translation unit, including the source text (ST), multiple translated texts (TT1, TT2, etc.), and their respective translation mappings (TM1, TM2, etc.).
    • Each translation mapping “debits” the source text and “credits” its corresponding translated text, ensuring a balanced and accurate representation of the translation process. Anything credited to the translation can be debited from the source text, and vice versa for full accountability.
  5. Reconciliation and Review:

    • Editors review the translation journal entries to ensure accuracy and consistency between the source text, multiple translated texts, and their mappings.
    • Discrepancies or issues are discussed and resolved, with the goal of creating a reconciled translation—there can be more than one accepted version for any unit, though a published version might be expected to arrive at a single preferred version for a given project—and mapping for each translation unit.
    • The reconciled translation and mapping are “posted” to the translation ledger, linking to the relevant journal entries.
    • The ledger entry represents a balanced translation that accounts for the credits, debits by way of the linking or mapping between the source and target texts.
  6. Reporting and Iterative Publishing:

    • Regular reports summarize translation progress, including the number of translation units processed, reviewed, reconciled, and posted to the ledger.
    • These reports can be used as a mechanism for iterative publishing, allowing the translation team to share their work in progress and gather feedback without the pressure of producing a finished product.
    • Iterative publishing helps maintain transparency, engage stakeholders, encourage believers, and refine the translation over time.
  7. Breaking Down Translation Units and Machine Translation:

    • The LT Framework enables the translation process to be broken down into smaller, manageable units, such as phrases or sentences, rather than focusing on larger segments like paragraphs or chapters.
    • As the translation progresses, the growing dataset of source texts, translated texts, and their mappings can be used to train and refine statistical and neural machine translation models.
    • These models can provide suggestions and assistance to translators, improving efficiency and consistency as the project grows.

By allowing for multiple translations and mappings to be submitted via the journal, and then reconciling them into balanced ledger entries, the LT Framework promotes collaboration and ensures that the final translation is a result of careful consideration and consensus.

The linking of ledger entries to their corresponding journal entries maintains a clear “audit trail” and allows for a comprehensive understanding of the translation process. This approach enhances transparency, accountability, and the overall quality of the translated text. More intriguingly, the LT Framework is a decentralized, collaborative, and iterative framework that does not rely on external expertise, and that can adapt to various translation projects, languages, and contexts, making it a valuable tool for emerging Bible translation projects and teams around the world.

Addendum: Simplified Implementation of Double-Entry Principles

While the full Ledger Translation Framework promises a robust approach to managing translations, a simplified implementation can still offer many of the benefits of double-entry principles.

In this simplified approach, translations are stored as both “journals” and “ledgers”:

  1. Translation Journal: The journal represents the raw, unadulterated translations, capturing the direct output from the translators. This includes the source text, the translated text, and any relevant metadata or notes.

  2. Translation Ledger: The ledger represents the reviewed, reconciled, and approved translations. It contains the final, polished versions of the translated text, along with the corresponding source text and metadata.

The process flow for this simplified implementation would be as follows:

  1. Translators create entries in the Translation Journal, providing their raw translations for each unit of text.

  2. Editors and reviewers assess the journal entries, making corrections, and ensuring consistency and accuracy.

  3. Once a translation is approved, it is transferred from the Translation Journal to the Translation Ledger, becoming an official, accepted version of the translation. Ledgers are versioned, journals are not - though they may be versioned via source control management software.

  4. The Translation Ledger serves as the authoritative source for the translated text, while the Translation Journal maintains a record of the original translations and the process of refinement. Because the ledger is versioned, translators are able to make updates to the journal entries, which can then be reviewed and re-posted to the ledger under a new version number. Theoretically, each verse may be versioned, or each chapter, or each book, or the entire translation.

By maintaining both a journal and a ledger, this simplified approach still provides transparency, accountability, and a clear audit trail for the translation process. It allows for the tracking of changes and the preservation of the original translator’s work, while also presenting a clean, approved version of the text for use and distribution.

While not as comprehensive as the full Ledger or Double-Entry Translation Framework, this simplified implementation still captures the core principles of double-entry bookkeeping and can be a valuable tool for managing translations in a more streamlined manner while maintaining transparency regarding the source texts used, the translation process, and the published and versioned translated text.

Permalink →

#translation #ai

One of the greatest hurdles to rapidly producing Bible translations is a misconception about what makes a quality translation. Everyone recognizes the importance of translation quality, but it is rare that someone can explicitly state how to measure quality or what level of quality is good enough for a first draft. It is likely that the more people you ask, the wider the range of answers you will receive. This is a problem because it is difficult to make progress on a project when the goal is not clearly defined.

In order to best leverage AI technology for drafting translations, it is necessary to be explicit about translation quality. AI works best when you can measure its results, and its translation results are no different.

With that in mind, I believe that translation quality is not determined by theological accuracy. The text of the Bible is theologically accurate, and so theological accuracy is a side-effect of translation quality.

Translation quality is determined by approximate semantic analogy.

  • Approximate means quality is not a binary value, but rather a cline which extends from worse to better quality.
  • Semantic means quality is a matter of meaning, not form
  • Analogy means that meanings may not be the same between cultures, but they may occupy a similar space in a coherent network of culturally bound meanings constrained by contextual factors in both the context of production and contexts of reception. A quality translation attempts to find better and better analogous meanings across languages.

There are three implications of framing quality in these terms.

  1. Iterative Quality is not a milestone, but an iterative process. Like a tree, translation quality may grow indefinitely and its limits are only imposed by the environment. As the environment changes, even a very high-quality translation may need to be updated.
  2. Indefinite Quality is non-definitive and non-final. There is no point at which one may say a tree is “finished” growing (though it may be big enough for your yard!). Translation involves coordinating between two moving targets, because languages are in a constant state of gradual change, and our understanding of the Greek and Hebrew texts is also in need of continuous re-evaluation as our own languages shift and our descriptions become inadequate.
  3. Uncontrollable One of the core values underlying the established process is control. The desire for tightly controlling the translation process comes from a righteous regard for the living and enduring revelation of God that we have in the very words of the Bible. For all this, it is a paternalistic attitude that imputes undue spiritual immaturity on believers around the world. It is also based on a misconception that we may know in advance the nature of the theological challenges that those believers will face as they read and wrestle with God’s word. The only preparation for dealing with bad theology in the future is the guidance of the Holy Spirit and a knowledge of church history.

God’s word has been given to us in natural human language. If our goal is to find the most approximate semantic analogies for its meaning, we will find that the theological accuracy of the resulting translations improves as a direct consequence. Perfection is often the enemy of good, and we cannot let the fear of imperfection paralyze us. While translation quality is essential, we must also simultaneously put ourselves in the place of those who have no Bible at all and recognize our insufficiency to translate with perfection.

Permalink →

Multimodal Language Server Protocol

2024-03-04 · 3 min read

#translation

The Multimodal Language Server Protocol (MLSP) is a protocol, based on the Language Server Protocol for communication between a language server and a client. It is designed to support the development of language servers that can process non-textual data.

Imagine being able to open an MP3 file in VS Code (or some other app) and have a server in the background identify, on the fly,

  • the language(s) spoken in the audio
  • characteristics of the speaker(s), their emotion, inflection, etc.
  • the words spoken
  • byte-based positions where you have spliced in edits
  • milestones or transition markers for navigation
  • etc.

And then, imagine if your language server could automatically clean out background noise on the fly, either for the whole file, or for byte-ranges you select in your editor using a waveform.

Key benefits

The benefits of an MLSP are the same as the LSP:

  • pushing heavy processes out of the client and into the background on a separate process
  • enabling the same server (whether local or remote) to be used by multiple clients

These twin benefits are especially important for multimodal language servers, which may require significant computational resources to process non-textual data. By breaking them out into separate processes, we keep the client responsive.

Major features

Like the Language Server Protocol, the MLSP would be designed to do two things:

  1. Publish diagnostics (error, warning, info, hint levels) for a given byte position range in the file
  2. Update the content for a given byte position range

Separation of concerns is of the utmost importance. These diagnostics and content updates are completely agnostic to what you are trying to do with your multimodal language server. All that matters is the kinds of client procedures that can be called remotely from the server, and the kinds of server procedures that can be called remotely from the client.

Adapation of LSP

The goal is to leverage the existing LSP as much as possible, only extending (or disabling/ignoring) features where it is absolutely necessary.

Conclusion

In conclusion, the Multimodal Language Server Protocol (MLSP) represents a significant leap forward in the development of language servers. By extending the capabilities of the traditional Language Server Protocol to handle non-textual data, MLSP opens up new possibilities for developers and users alike. Whether it’s processing spoken language in audio files, identifying speaker characteristics, or automatically cleaning background noise, MLSP has the potential to revolutionize the way we interact with digital content. I’m excited to continue exploring and expanding the boundaries of what language servers can do.

Reach out to me at ryderwishart at gmail dot com if you’re interested in contributing to the project.

Permalink →

Beyond Word Alignment

2024-03-01 · 2 min read

#translation #linguistics

“It is impossible to study patterned data without some theory, however primitive. The advantage of a robust and popular theory is that it is well tried against previous evidence and offers a quick route to sophisticated observation and insight. The main disadvantage is that, by prioritizing some patterns, it obscures others. I believe that linguists should consciously strive to reduce this effect until the situation stabilizes.” (Sinclair, “Trust the Text,” 10)

This quote outlines the situation with biblical linguistics: it’s easier and faster to get to sophisticated observation, but you wind up obscuring the things your theory didn’t account for.

When it comes to alignment, we’ve been so busy focusing on one particular unit, the word, that we haven’t paused to think through what is it that we are not focusing on, and what we are missing out on by adopting this focus.

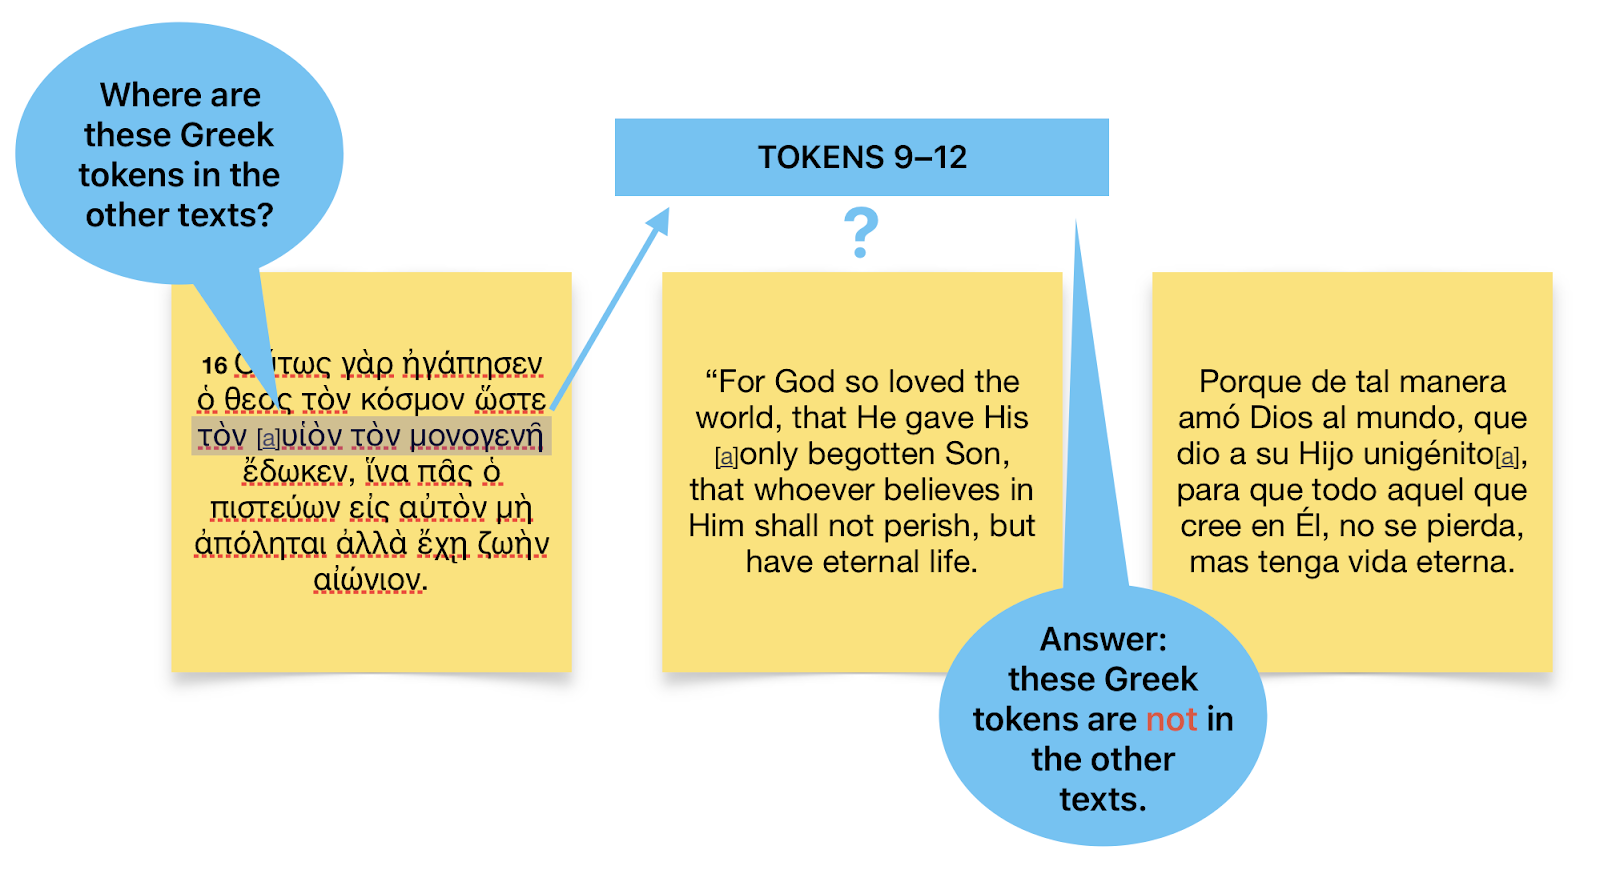
The major downside to word alignment is that a word is not a translation unit; it is a linguistic structure, and structure is precisely the thing that you leave behind when you translate a text.

Permalink →

#translation

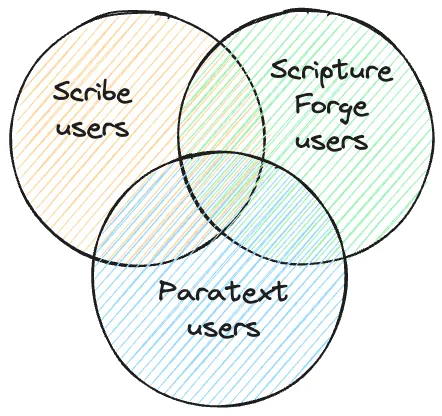
🔍 Context: The Bible-translation world has spawned a number of specialized editors, each catering to a unique set of users. This multiplicity ultimately serves the translators, ensuring that various needs are meticulously met.

Sets of users

🔧 The Challenge: Each translation editor requires custom-built tools. While this tailoring offers specific solutions, it creates a siloed ecosystem.

Isolated tools

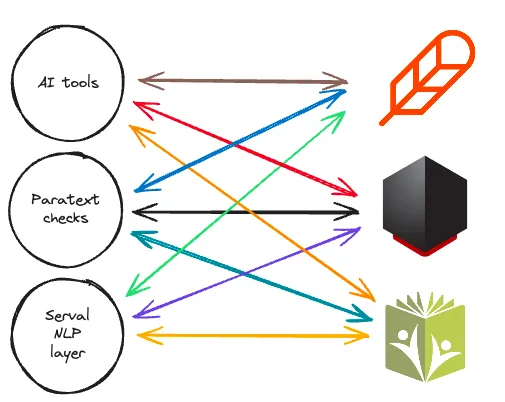
Integrating these tools across different editors can lead to a complex web of interfaces and contracts, muddying the waters of maintenance and ownership clarity.

Integrated tools with too many contracts

🤔 The Question: How do we combine our efforts while simultaneously maintaining a multiplicity of editors and avoiding the pitfalls of overcomplication and lack of clear ownership?

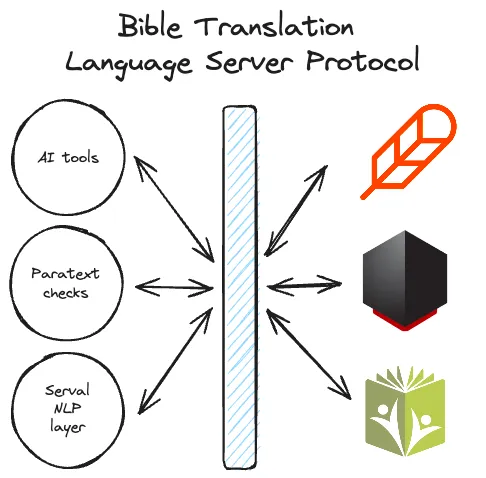
💡 The Insight: Imagine a world where every translation editor could use every new tool that was built right out of development. This could be possible if we all followed the same protocol.

🚀 The Solution: A Shared Protocol for Translation Tools

The world of programming has already found a solution to a similar problem: the Language Server Protocol (LSP). This protocol standardizes the communication between editors and tools, ensuring seamless interaction without the need for custom tooling for each editor.

A Bible Translation Language Server Protocol

In short, the LSP allows tools to work across multiple editors, eliminating the need for custom development for each environment. This not only simplifies maintenance but also allows for more efficient use of resources and ensures scalability for future needs.

LSP provides a standardized way for tools to communicate with different editors, simplifying the integration process. To put it in the words of the LSP designers, “LSP is a win for both language providers and tooling vendors!”

💡 Benefits of LSP in Translation:

Just as in programming, where tools and editors align with the Language Server Protocol (LSP), translation tools too can benefit from this approach.

  1. Streamlined Communication: LSP ensures that all tools speak the same language, making it easier for them to work seamlessly with various editors.
  2. Reduced Complexity: By adopting a common protocol, the need for multiple, unique interfaces is eliminated, thereby reducing maintenance challenges.
  3. Clear Ownership: With LSP, boundaries between different pieces of software are well-defined, clarifying responsibility and ownership without sacrificing integration.
  4. Enhanced Collaboration: A unified approach fosters better collaboration and knowledge sharing among different tool developers.
  5. Future-Proofing: LSP is a forward-thinking solution, allowing for easier upgrades and integrations as new editors and tools emerge, since even when new editors or tools are introduced, they all follow the same protocol.

How does it work?

If you want to read more about the LSP in general, check out the official documentation. We’re implementing a language server that follows this protocol for Project Accelerate, and we would love to see the community adopt something like this protocol as well.

🎯 Conclusion

Incorporating the LSP into our translation tools aligns us with a proven method in the programming world. It offers a solution that respects the differences between editors, their teams, and their user bases, while greatly simplifying the tool-integration process. This not only enhances efficiency but also ensures a more manageable and scalable system for all involved.

📣 The Call to Action:

Let’s embrace the idea of a Language Server Protocol. By doing so, we uphold the unique value of each translation editor, while bringing clarity and ease to the tool integration process. This strategic move will keep us agile, focused, and ready to meet the evolving needs of the translation community with an ever-growing suite of tools.

Updated March 4, 2024: Clarified that we should simply aim to use the LSP, not create a new one.

Permalink →

Linguistic Anomaly Detection

2024-01-01 · 3 min read

#translation

Linguistic Anomaly Detection is a technique for similarity scoring (compression-based, embedding-based, or traditional NLP-based) between source-source and target-target pairs. This involves comparing the similarity of source texts and their corresponding target texts. Rather than being scored against a baseline, however, it has the essential feature of being relativized to the current state of the translation project, such that only the verses a human has already translated/edited serve as the gold standard. Here’s an idea for how LAD might work in a translation project:

  1. Suppose you have a source1-target1 pair that has been manually vetted and is considered the gold standard.
  2. You also have a source2-target2 pair that has not been vetted yet.
  3. Compare the similarity of source1 and source2. This could involve comparing the compression results or similarity between the sources and between the targets, doing TF-IDF intersection scoring against your current project, or some other method.
  4. If the similarity between source1 and source2 is 0.8, then the similarity between target1 and target2 should be within a standard deviation of 0.8. (This is my suspicion at least.)
  5. Provide Scores or Reports on Estimated Consistency: The above technique (or a variation thereof) could be used to provide scores or reports on the estimated consistency for the unvetted target text (target2). This allows for a quantitative measure of the translation’s internal consistency, and by implication it should indicate something about its overall quality.

There’s a lot of room for variation here, but the basic idea is to use a partially complete translation to evaluate the consistency of the rest of the translation. This is a very different approach from the traditional BLEU score, which compares the translation to a baseline (e.g., a human translation or a machine translation). Traditional approaches require you to have a baseline and hypothesis (i.e., two separate versions) for the specific text you are translating. This approach only requires you to have a single target rendering. Instead, this approach compares the translation to itself, which, in my view, is a much more useful metric for translation quality assessment in the first place, since it doesn’t necessarily prioritize word-for-word equivalence, which can be deceptive as a quantitative metric.

Permalink →

Few-shot Translation Evaluation

2023-12-22 · 2 min read

#translation #ai

In the context of a translation project, where we aim to utilize only the resources at hand, let’s consider a simplified approach to the evaluation stage. This approach would involve the following steps:

  1. Start by taking the draft translation and identify the translation pairs that are most similar to the paired prediction.
  2. Evaluate the draft translation for any potential misuse of words.
    1. One possible method could be to use a rules-based matcher that identifies any tokens in the source+prediction pair that only occur in EITHER the source OR the target in any of the similar examples.
    2. It could also be beneficial to examine whether any words seem to be mistranslated based on the gold standard examples.
    3. To aid this process, aligning these examples by phonetics, orthography, and apparent semantic similarities could be helpful.
  3. Once the evaluation is complete, pass the task back to the translation bot, providing special notes about any words that appear to be mistranslated.

In essence, the process can be summarized as: [ most similar examples ] —> [ prediction ] —> [ most similar examples ]

The goal is to identify the most similar examples to the prediction, and then use those examples to evaluate the prediction. This process can be repeated iteratively, with the bot learning from the evaluation and then generating a new prediction and a new set of examples that will help the initial bot improve its output.

Permalink →

Multi-Agent Translation Simulations

2023-12-22 · 5 min read

#translation #ai

It ought to be possible, in some scenarios (particularly resource constraints and model availability) to run a continuous multi-agent simulation to iteratively improve a draft translation. One example I’ve implemented involves the following basic loop (each step is not necessarily blocked by the prior step):

  1. Main translation loop
  2. Forward translation bot drafts a new translation instance using few-shot learning based on the available example translations drafted so far by humans
  3. Back-translation bot provides a back-translation of the new instance
  4. Evaluation bot provides feedback on how to improve, correct, or revise the instance repeat process until the translation draft stabilizes (if it does!)
  5. Linguist bot builds and updates language resources, such as a multilingual project lexicon, a working grammar, machine grammar rules for output token biasing with the LLM, etc.
  6. Project manager bot brings stable drafts to human translation team for input, feedback, and correction. Corrected drafts are added to the pool of examples available to the main translation loop.

Here’s a sample implementation I created back in June 2023. It doesn’t actually go anywhere in the video, because every bot is waiting for the other bots to start!

Here’s the sample configuration file for the demo I made:

{
    "world_name": "Bible Translation Project",
    "locations": [
        {
            "name": "Bot Room",
            "description": "A virtual space where the translation bots work together to translate and evaluate the biblical text."
        },
        {
            "name": "Project Management Office",
            "description": "A physical space where the Project Manager Bot interacts with humans to get feedback and guide the translation process."
        }
    ],
    "agents": [
        {
            "first_name": "Translation Bot",
            "private_bio": "Translation Bot translates biblical text from Greek and Hebrew into the target language, using various resources for assistance.",
            "public_bio": "Translation Bot is a language model that translates biblical text from Greek and Hebrew into the target language.",
            "directives": [
                "Translate verses from source to target language.",
                "Consult other translations as needed.",
                "Access relevant language data for translation."
            ],
            "initial_plan": {
                "description": "Translate the source text into the target language.",
                "stop_condition": "The entire source text has been translated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_access", "similarity_search", "feedback_processor"]
            }
        },
        {
            "first_name": "Back-Translation Bot",
            "private_bio": "Back-Translation Bot provides a back-translation of the draft translation for evaluation purposes.",
            "public_bio": "Back-Translation Bot is a language model that provides back-translations of the draft translations.",
            "directives": [
                "Back-translate the draft translations.",
                "Access relevant resources except the actual source text."
            ],
            "initial_plan": {
                "description": "Back-translate the draft translations into the original language.",
                "stop_condition": "All draft translations have been back-translated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_access", "similarity_search"]
            }
        },
        {
            "first_name": "Evaluation Bot",
            "private_bio": "Evaluation Bot evaluates the back-translations and provides feedback for revision.",
            "public_bio": "Evaluation Bot is a language model that evaluates the back-translations and provides feedback.",
            "directives": [
                "Evaluate the back-translations.",
                "Generate questions and inferences about the draft translation.",
                "Synthesize results and provide revision directives."
            ],
            "initial_plan": {
                "description": "Evaluate the back-translations and provide feedback.",
                "stop_condition": "All back-translations have been evaluated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "question_generator", "inference_generator", "MACULA_API"]
            }
        },
        {
            "first_name": "Project Manager Bot",
            "private_bio": "Project Manager Bot manages the entire translation project, interacting with humans for feedback and guiding the bots.",
            "public_bio": "Project Manager Bot manages the entire translation project and ensures the bots follow the translation brief.",
            "directives": [
                "Manage the translation project.",
                "Track the translation brief.",
                "Interact with humans for feedback."
            ],
            "initial_plan": {
                "description": "Manage the translation project and ensure bots follow the translation brief.",
                "stop_condition": "The translation project is completed.",
                "location": "Project Management Office",
                "tools": ["feedback_processor", "Human_Feedback_Tool"]
            }
        },
        {
            "first_name": "Linguist Bot",
            "private_bio": "Linguist Bot collaborates with Translation Bot to build and update language resources, creating a multilingual lexicon and describing key patterns of the target language.",
            "public_bio": "Linguist Bot works with Translation Bot to enhance language resources and ensure the accuracy and sensitivity of translations.",
            "directives": [
                "Collaborate with Translation Bot in building language resources.",
                "Create a multilingual lexicon.",
                "Describe phonological and morphophonemic patterns of the target language."
            ],
            "initial_plan": {
                "description": "Collaborate with Translation Bot and update target language resources.",
                "stop_condition": "The translation project is completed and all language resources are updated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_updater", "lexicon_builder"]
            }
        }
    ]
}
Permalink →

#translation

Linguistic structures are the formal patterns that realize linguistic meanings. In the process of translation, it is the meanings that are translated; the structures are left behind by design. Semantics are the priority in translation.

Note: between two languages, the semantic systems are not isomorphic. This mismatch means that we cannot assume that the precise semantic categories of one language may be transferred into another. Comparing the lexicogrammatical systems of gender in two languages should suffice to illustrate this point. However, the general semantic categories seem to be fairly universal (one would have to compare every language to actually establish this claim).

This fundamental observation must be factored into the translation process as we consider how AI tools might be leveraged for translation drafting.

For instance, rather than trying to account for every word in the source by translating a word in the target, we should attempt to account for the things the words are being used to realise, namely the entities, processes, traits, collocations, logical sets, speech acts, and more.

It is definitively better to traffic in semantic units such as these, since accounting for such meanings is what makes a translation good or bad.

By contrast, imagine if someone claimed that you needed to account for every character in the source text (all the alphas, omegas, deltas, and iotas). If you did somehow manage to do this, you would not be translating, but copying.

Permalink →

Reranked Translation Suggestions

2023-12-22 · 4 min read

#translation #ai

In the field of machine translation, ensuring the accuracy and context-relevance of translations is critical. One approach to address this challenge is through the use of semantic similarity between source verses as a tool for suggesting a disambiguated rendering from multiple possible options. (example below)

This idea, which I will refer to as “Reranked Translation Suggestions”, can be particularly effective when dealing with semantic units, but it can also be implemented with words only.

A Practical Example

Consider two translation units:

  1. “Jesus walked on the water” -> “Jesus walked on the big blue wet thing”
  2. “Jesus said, give me some water to drink” -> “Jesus said, give me some drinking stuff”
  3. “Peter walked on the water” -> “Peter walked on the ?”

Let’s imagine that in the target language, the source word ‘water’ is translated as ‘big blue wet thing’ in the first verse and as ‘drinking stuff’ in the second verse.

In this scenario, a dictionary is updated to note that there are two possible renderings of the ‘water’ entity (this is a semantic unit that is not a process, not a trait, etc.—see below) in the source, and it notes the verse context for each rendering.

Later, when a rendering for ‘water’ is needed, the method checks the new source verse and determines whether the new verse is most similar to the verse that uses ‘big blue wet thing’ or the verse that uses ‘drinking stuff’. The most likely option from the project dictionary is then suggested accordingly.

Put even more simply, the method uses semantic similarity between the original verses to determine which of the two renderings for ‘water’ is most likely to be the correct rendering in the current verse.

“Peter walked on the water” is a new verse that has not yet been translated. The method can suggest the two possible renderings for ‘water’ based on the two previous verses, and then the translator can choose the most appropriate rendering for the current verse. In this case, the translator would likely choose ‘big blue wet thing’ as the most appropriate rendering for ‘water’ in this verse.

By leveraging semantic similarity and understanding the context of the source verses, this method can significantly improve the accuracy and relevance of translation suggestions, leading to more precise and contextually appropriate translations.

In short, translation suggestions can be “reranked” based on semantic similarity between the source verses.

Special Note on Semantic Units

Semantic units are often deeply nested. For example, “Jesus” is an entity, “Christ” is an entity, and “Jesus Christ” is an entity as well. When working with glosses for semantic units, each glosses should be assumed to refer to the largest entity in nested entities and all children until there is a separate case where there’s only partial overlap between the source and target. Previous glosses apply to these semantic units, further refining the translation suggestions.

For example, assume I have a semantic dictionary in which I know the “Jesus” has gloss A, “Christ” has gloss B, and thus “Jesus Christ” cannot be simply assigned either gloss A or B. On the contrary, if “automobile” has gloss C, then the high-level entity “the automobile” might be assigned gloss C as well, since it has no inherent conflict in its constituent children (assuming ‘the’ is simply a grammatical marker that shouldn’t always be glossed).

This seems a bit abstract at the moment, so I’ll give a more concrete example in the future. See also Multi-Agent Translation Simulations for another approach to improving translation accuracy.

Permalink →

#translation #ai

Here’s an idea I had for translation quality checking.

The process begins by prompting for a translation using n examples and a directive to complete the translation pairs. The entire prompt, along with the AI’s completion, is then passed to the evaluator. The evaluator’s task is to determine which translation was generated by the AI. This may require fine-tuning a discriminator model on the gold-standard pairs.

The concept, inspired by Generative Adversarial Networks (GANs), involves an evaluator attempting to distinguish AI-drafted translations from a list of real translations. While it doesn’t function exactly like a GAN, the idea is to use a similar principle for evaluation.

The method could potentially be used to refine the prompts or the models themselves, by replacing the evaluator with a separate AI. Initial implementation will use Language Models (LLMs) to gauge the viability of the concept. If successful, this approach could be extended to train GANs for specific languages.

Permalink →

#translation #ai

In the realm of machine translation, achieving the highest level of accuracy is paramount. One approach to improve the precision of translations is through a method called “Token Matching Evaluation”. This method centres around the use of valid tokens, which are words or phrases that have appeared in sample translation pairs.

The Process

  1. Populate a list of valid tokens for back-translation: The first step is to create a list of valid tokens. These tokens are the words or phrases that the model is allowed to use for back-translations.

  2. Back-translate using valid tokens: The model is instructed to back-translate any given word only from the list of valid tokens. For example, using the {{select options=valid_tokens n=6}} syntax, the model selects a specific value from a chunk of 6 valid tokens.

    • If a word hasn’t even been translated once by a human, then any attempt would effectively be indistinguishable from a hallucination. Therefore, it is important that the valid tokens correspond to reality. For instance, if you need to translate the English word ‘Jerusalem’, you would find 5 sentences with ‘Jerusalem’ in them and those sentences would have Abanyom renderings, like ‘Yerusalem’. The only valid renderings must be contained in the sample sentences.

    • Any tokens not in the set of valid tokens are simply retained in their translated form in [square brackets] to indicate they have not been back-translated because they are unknown. This could be facilitated by having an agent send out messages to the translation team via WhatsApp, or using a simple gamified app.

  3. Gather samples based on token coverage: It might be beneficial to gather samples based on whether or not they help cover the missing tokens. Start with an initial set of 5 semantically similar examples, followed by a second set of 5 more sentences that include the English glosses not represented in the first five examples.

By following these steps, the output translation will more likely align with the sample translations provided in the prompt, thereby enhancing the accuracy of the translation.

Permalink →

AI and Low-Resource Translation

2023-12-22 · 5 min read

#translation #ai

For any machine translation technique to succeed requires lots of data. When it comes to low-resource languages, you simply don’t have lots of data. For this reason, we need to explore other methods and techniques that are somewhat orthogonal to the traditional approach of training a model on a large corpus of data.

Many AI-based translation approaches are based on the idea of transfer learning. This is where you train a model on a large corpus of data, and then fine-tune it on a smaller corpus of data. The idea is that the model will have learned some generalizable features from the large corpus, and then it can learn the specific features of the smaller corpus. This is a great approach, but it still requires a large corpus of data to train on.

Ultimately, we’re going to need something quite different to achieve high-quality translation for low-resource languages.

Opening up the black box

One of the biggest challenges with AI-based translation is that it works like a black box. You feed in some data, and you get some data out. But you don’t really know what’s going on inside the black box. You don’t know what the model is learning, or how it’s learning it. You don’t know what features it’s learning, or how it’s combining them to produce the output. This should rightly make translators somewhat nervous. How can you trust the output of a model that you don’t understand?

My vision for translation assistance with AI is thus to pry open the black box by using LLM-based predictions, rather than simple sequence-to-sequence predictions. This is a fundamentally different approach, and it relies on the concept of in-context learning, rather than a fine-tuning or transfer learning approach.

In-context learning

In short, in-context learning involves providing “training data” to the model on the fly, in the prompt. (Read more from Stanford AI Lab).

This is a fundamental difference that is really critical for translation assistance. It means we don’t need to take a bunch of data (e.g., a complete New Testament translation) in order to fine-tune a model for generating more data (e.g., a complete Old Testament translation). Instead, we can take a small amount of data (e.g., a few verses of the New Testament) and use it to generate more data (e.g., the next few verses of the New Testament, or some similar verses being drafted in the Old Testament).

We get two big benefits from this approach:

  1. Bootstrapping: We can use a small amount of data to generate a large amount of data. This is a huge benefit for low-resource languages, since we can use the data we have (which is not enough for fine-tuning a model) to generate more data, and then use that new data (again, without re-fine-tuning our model) to generate even more data, and so on. This is a virtuous cycle that can help us bootstrap our way to a complete translation.
  2. Instant feedback: We get instant updates, allowing the real translator (a human), to provide feedback to the model on the fly.

What do we need to make in-context learning work throughout the translation process?

To leverage in-context learning, we need to be able to draft new translations using few-shot examples (e.g., use a few already-translated verses to draft a new verse). We also need to be able to evaluate those translations using few-shot examples (e.g., use a few already-translated verses to evaluate a new verse). Optionally, we might want or need a back-translation in order to enable third party evaluation (such as a translation consultant).

Working backwards, then:

  • To evaluate, I need
    • a metric
    • [optional] a back-translation
  • To back-translate, I need
    • a translation
    • a non-hallucinating technique
  • To translate, I need
    • a chunk type (a unit of translation)
      • could be a Bible verse
      • could be a larger semantic unit that looks like a phrase
      • I would not recommend using a single word, since a word is a structural unit, and structures are precisely what gets left behind in translation
    • a source text
    • few-shot examples
    • [optional] supporting data
      • glossary
      • notes
      • evaluation feedback on prior drafts
    • [optional] constrain with valid_tokens
    • [optional] a concise, prosaic description of the most relevant source language data
    • [optional] a concise description of the language-typological differences between the source and target languages

Conclusion

Translation assistance can leverage LLMs and in-context learning to open up the black box of AI-based translation. This approach can help us bootstrap our way to a complete translation in a manner that cannot be achieved using traditional machine translation and typical AI-based approaches such as sequence-based model fine-tuning, and it can accept instant feedback from the translator, which means that every single correction or improvement made by the translator gets leveraged in the very next verse or chunk being drafted.

Note: you can also use an approach like this for a multi-agent simulation. See also the Social Approach to Low-Resource Language Translation.

Permalink →

#translation

If you are working with Bible translation data, you know how challenging it can be to deal with different types of data sources, formats, and structures. You may have to spend a lot of time and effort to model your data in a way that makes sense for your specific use case, whether it is creating a graph, a relational database, or a document database. 😒 But what if there were a better way? What if you could focus on gathering and integrating more data, without having to make all the decisions up front about how to model it?

A simple database-like interface

That’s the idea behind a simple database-like interface that we have been exploring recently. It is based on the principle of 🔥 “more data, and less decisions about data”. ✨ The interface allows you to link together many types of wide-column datasets in various formats, such as JSON, XML, plaintext, and even audio, image, etc. Every file can be a first-class citizen 🫡, and files may make reference to other files or indexes within other files. ☝️ This way, you can create a rich and flexible data-lake that can store and access any kind of data you need.

The advantage of this approach is that you don’t have to worry about how to schematize everything in advance. You can start with the raw data you have, and then build on top of it as you go. You can create graphs or relational databases on top of this NoSQL data, using queries that can join and build complex structured implementations. And the best part is that you can reuse these queries and store them forever, so that you don’t have to repeat the same work over and over again. For example, you can create an alignment between two languages, and then include IDs or vectors that allow you to tunnel through to image data, audio Bible segments, or key paragraphs in commentary texts.

Persisting joined data

How do you keep the joined or queried data around indefinitely? You just save it in a new JSON file and plunk it into your folder along with all the original data.

While the idea of saving the joined or queried data in a new JSON file and adding it to your folder along with all the original data might seem straightforward, it’s important to consider the potential confusion this could cause in the long run. Just as saving different versions of a document with abstract names can lead to confusion about which version is the most recent or correct, the same can happen with data files.

To avoid this, one might utilize some simple metadata in a README file and mapping the origins of data. A simple solution could be to always include the script that created the data, with the script pulling its sources from a specific commit of another repository. This way, the “version” of the data can always be tracked. If a core repository is updated, all other repositories using the old commit can regenerate their data. This process could potentially be automated as a GitHub action that appends a list of added/updated files to the README (which would in theory include the creation script and associated output files).

These updates could be documented in the README, ordered by recent updates. This would provide a clear record of all new files added, optional descriptions, and timestamps for when files were created or updated, along with the commit hash.

Summary

This is not a new vision of a kind of database—it’s probably just a NoSQL database. Maybe we could call it an Agile Data Hub. 🤔 Whatever you call it, the application for Bible translation data is important, since we’re talking about many kinds of structured and unstructured data, especially in light of our ability to inexpensively extract structured data using LLMs. By using this simple database-like interface, you can speed up your delivery times and workflows, and leverage more data without making more decisions. Isn’t that what we all want?

Note: This post was inspired by recent experiences trying to create an alignment POC for Tok Pisin, and a subsequent schema-brainstorming session with Ben Scholtens. Thanks, Ben!

Permalink →

#translation

(A Dynamic Equivalence Alignment is something like “Essentially Aligned Bible Translations”)

Token to token mapping is problematic, despite its ubiquity. It is theoretically the same as character to character mapping (a token is, with some exceptions, a set of characters delimited by whitespace). There is a fundamental distinction between structural units like characters, tokens, phrases, clusters, wordings, sets, etc., where the defining characteristic is composition (“what is this thing built out of?”) and semantic or functional units like entities, processes, predications, speech acts, definitions, scenarios, etc., where the defining characteristic is role or function (“what does this thing do in its immediate context?”). 

With regard to alignment, the question driving any alignment is “what does span A have in common with span B?

The answer depends on what type of spans you are trying to align. 

Span typeSpan A is…Span B is…Both spans have in common…What type of similarity is this?Does ER++ gold standard alignment data get it right?Does the SOTA algorithm get it right?
CharacterκaNothing obviousSuperficialn/an/a
ωoSome kind of non-meaningful phonological similarityn/an/a
TokenκαὶasNothing obvious.Depends on the type of token.nono
ὁtheGrammatical (sort of) and semanticnoyes
ἔπεσενfellGrammatical (partial) and analogous lexical semanticsyesyes
Formal Syntactic Structureκαὶ ἐγένετο… (clause)as he was… (adverbial phrase)Partial lexical, partial grammaticalDepends on how similar the two languages’ grammatical systems are.nono
ἐν  τῷ  σπείρειν (prep. phrase)scattering (part of compound verb ‘was scattering’)noyes
Semantic unitἐγένετο (event)he was (event)Semantic categoryA meaningful semantic unitnono
ἐν ταῖς πορείαις αὐτοῦ (circumstance)in the midst of his pursuits (circumstance)Semantic categoryn/an/a

The case against token mapping as a basic strategy

Let’s assume that tokens are whitespace delimited, though this is not a necessary condition for the argument I want to make here. My argument is this: we should attempt to map semantic or meaning-based similarity instead of formal or structural similarity, because semantic overlap is implied by a translation, while formal overlap is explicitly repudiated (otherwise no translation would be necessary, or the task would be simple deciphering, as in an interlinear).

The issue with trying to map tokens between texts of different languages and/or translation styles (even within the same language) is based on the fact that a “token” is a formal category, and there is no principled linguistic or theoretical reason to assume that a token in language 1 will correspond isomorphically to a token in language 2. This is related to the use of whitespace to delimit tokens, but any tokenization strategy could fall prey to the same problem. Conversely, using whitespace delimited tokens is in fact a possible path forward, but the crucial hurdle to overcome is that we must not think of our task as one of aligning formal structures. 

Consider the very nature of translation as a human activity. When one translates from text A to text B, the task is not to create a more-or-less graphically isomorphic re-presentation of text A in text B. The success of the task does not require there to be any structural or formal isomorphism between the two texts. Consider the following “translation” of John 3:16 into English (The Message), Chinese (CSB), and Arabic (KSS):

Source: For God so loved the world that he gave his only begotten son, that whoever believes in him should not perish but have everlasting life.

Target 1: This is how much God loved the world: He gave his Son, his one and only Son. And this is why: so that no one need be destroyed; by believing in him, anyone can have a whole and lasting life.

Target 2: 因为上帝爱世人,甚至将祂独一的儿子赐给他们,叫一切信祂的人不致灭亡,反得永生。

Target 3:لەبەر ئەوەی خودا ئەوەندە جیهانی خۆشویست، تەنانەت کوڕە تاقانەکەی بەختکرد، تاکو هەرکەسێک باوەڕی پێ بهێنێت لەناو نەچێت، بەڵکو ژیانی هەتاهەتایی هەبێت،

What is the one thing that none of these translations have in common? Structural isomorphism. There are degrees of formal similarity between them (somewhat similar overall length? Perhaps there are some similar phonological patterns (though I can’t tell, not knowing all the scripts). There are more formal similarities between the English versions, but this is, I would argue, only superficial. The reason these are translations (or perhaps we prefer the term paraphrase for same-language translation) is because they have semantic overlap. 

You cannot find any of the Greek tokens in either the English or Spanish texts!

Once we move to separate scripts, I hope it becomes clear that it is not a useful question to ask “Where does the word ‘God’ in the source appear in each of these target texts?” The word “God” does not appear in the other texts—that’s the whole point of translation. What we should be asking is something like “Where does the entity construed via the word ‘God’ get construed in the other texts?” This is a subtle difference, but it’s the difference between being able to answer the question and being stuck trying to accomplish a task that we are not well equipped to do in a scalable and reliable manner, and for which we have no formal evaluation apparatus.

When it comes to aligning whitespace-delimited tokens, just because it’s the state of the art, does not mean it is reliable or scalable, and it doesn’t mean we can’t do better with tools we already have.

Our gold standard data is not as reliable as we would like it to be. In addition, Clear Engine’s alignment relies on token-to-token alignment, and it is far from reliable out of the box. Even when improved by structure-based segmentation of units, the structures that each language uses to realize its semantics are always divergent to some degree.

Proposed path forward

The most basic implementation of semantics-based alignment for our purposes could take three forms (and these could also be combined into a single approach).

I think we should really pursue Option 3, since it best accords with the broader theoretical conception of translation, and it is likely to be even more useful than a word-level alignment in terms of the kinds of resources that can be retrieved.

Option 1: drop function words (pretty easy)

First, we can pursue the essentially aligned Bible translations approach. Initially this might mean we simply drop the so-called function words from the source language, and attempt to identify matching content words in the target languages. The downside of this coarse approach (i.e., simply dropping words we suspect will not be important), is that there are many likely exceptions. For example, a single Greek verb ἦλθον would align best with two English words “was going.” 

Option 2: replace source text words with glosses or lemmas (easiest?)

Second, we could use language-specific glosses for aligning to another language. We have English and Mandarin glosses for our Greek and/or Hebrew texts, and I suspect we can much more easily align and automate evaluation for the alignments between an ‘interlinearized’ English string. For example,

  • Greek: καὶ εἶπεν αὐτοῖς Ποῖα;οἱ δὲ εἶπαν αὐτῷ Τὰ περὶ Ἰησοῦ τοῦ Ναζαρηνοῦ,

  • English glosses: And He said to them What things; - And they said to Him The things concerning Jesus of Nazareth,

The English glosses in the above example are probably more straightforward to align to English translations. These glosses can then be decoded back into the Greek text from which they were generated.

Option 3: treat alignments as annotations (best)

Third, and more ideally, we would think about alignments as what they really are, just another form of annotation, where text A is “annotated” with text B. 

As the figure above illustrates, an annotation like “a semantic unit representing an entity” can be annotated across languages. It does not assume that the tokens in any language correspond isomorphically to tokens in another language, yet token- and character-level alignment is implicated by semantic alignment! I believe this is the best approach to alignment of the options listed above. 

This approach can be technically implemented by indexing the spans in each text that should be annotated with each semantic annotation. This means we do not need to even use IDs for alignment—alignment can be a character-level annotation — because the things being aligned (e.g., the blue rectangular box in the figure above) are not tokens. 

Summary

Let us make it our explicit goal to align meanings, not forms. The meanings are realized in forms, but the nature of the question changes because we are mapping form->meaning->form (which can be more or less objectively evaluated) instead of form->form (which implies the meaning without making it explicit). 

Our goal should not be to align: FORM → FORM

Our goal should be to align:

FORM → MEANING → FORM

ApproachAlignment taskImplementation
Formal or structuralFORM → FORM
e.g.,
character → character
token → token
whitespace break → whitespace break
Language-specific tokenization.
Every text must be parsed into individual forms that are as similar as possible to our Greek tokens to try to compare apples to apples
- Greek is whitespace tokenized (+/- punctuation)
- Hebrew is broken down to subword levels to try to match the Greek
- Chinese? Arabic? Malayalam?
Semantic or functionalFORM → MEANING → FORM
e.g.,
index → entity → index
index → process → index
index → circumstance → index
index → speech act (e.g., statement | command | question | request) → index
Meaning is linked to string index ranges in any text we want to align
- We identify meanings in the source text (or fall back to phrase structures if we do not have meanings, e.g., for Hebrew)
- Meanings are indexed to arbitrary character spans in the source text file (e.g., Mike and Ben’s suggested implementation)
- Meanings can be subsequently indexed to arbitrary strings in any text. This means that form-to-form mapping is implied by form-to-meaning-to-form, without the problematic aspects of trying to create a dataset that shows where Greek tokens appear in English texts, etc.
Permalink →

#ai #translation

Building an AI-native translation app

We’re exploring the idea of using AI agents, via simple user interfaces, as a way to orchestrate Bible translation tasks both within an app and by leveraging outside tools and APIs.

While we’re still in the early stages of this exploration, we’ve already found that it’s possible to build a Bible translation app using VS Code as a base.

Our proof-of-concept plugin has one simple task: when the user says “the right way to say X is Y”, the plugin will discern the user intent and update the lexicon.txt file (the project’s dictionary).

What we want to do next is to use the AI agent to orchestrate the translation process, to take the next step of suggesting updates on any verses that are implicated in the lexicon change.

This is where VS Code comes in.

We realized we can use VS Code as a base for a Bible translation app. It’s open source and has a lot of features that you would need for a Bible translation app. It’s also very extensible, and operates at the highest echelons of enterprise software, and can be localized into many languages of wider communication (e.g., the Chinese localization has over 24 million downloads!).

How feasible is it to fork VS Code?

Providentially, we have an example of someone forking VS Code and building a fully functional AI-native app. A huge congratulations to the folks at Anysphere/Cursor. This app is awesome.

The craziest thing about this is that they did it in a matter of months, with a small team of developers (I think it was 2-3 or so people). They forked it in March 2023, and I tried the app in July, and it rocked.

I think there are some learnings to gather here for the Bible translation world: VS Code provides a great base for building an AI-native app, and it seems feasible to fork it and build something that is useful for translators by leveraging the fact that VS code has done all of the hard stuff already (like mature source control, tested localization, an impressively stable architecture with over 51K published plugins, live sharing for instant remote collaboration, and more).

Adding translation functionality suddenly seems like a small task in comparison.

Permalink →

#translation

When it comes to language translation, particularly for low-resource languages, AI has a lot of potential for providing new solutions. Recently, I presented a “social” model, aiming to mimic the roles and interactions within a human translation team using a Generative Adversarial Network (GAN) structure plus AI agents. This approach consists of several agentive AI roles - the translator, back-translator, evaluator, and possibly a project manager.

The Social Approach

In the social approach, each AI agent takes on a role in the translation process:

  • Translator: The translator agent’s role is to translate the text from the source language to the target language. It’s trained to generate translations that are as close as possible to the target language’s natural language usage.

  • Back-Translator: The back-translator receives the output from the translator and translates it back to the original language. This helps ensure that the meaning of the text is preserved in the translation process.

  • Evaluator: The evaluator compares the original text and the back-translated text to assess the quality of the translation. It might use metrics like BLEU or other language-specific criteria to provide a quantitative measure of the translation’s quality. It could also generate qualitative questions about the draft translation and attempt to answer those questions issuing a variety of tools (as in LangChain tools).

  • Project Manager (Optional): This role could manage feedback from external stakeholders or experts, providing a higher-level, holistic evaluation of the translation. It’s responsible for integrating this feedback to guide the other agents.

Contrast with Swarm and Hive-Mind Approaches

Unlike the swarm-based and hive-mind approaches, which are inspired by natural systems and involve agents working in parallel, the social approach is structured around a sequential workflow, imitating human processes. Each agent has a distinct role and tasks are performed in a specific order.

In the swarm-based approach, multiple agents work on different aspects of the translation or different subsets of the data, combining their outputs for the final translation. In the hive-mind approach, each agent is fine-tuned on a specific aspect of the language, with the final translation being a combination of all outputs.

The social approach, on the other hand, leverages the adversarial nature of GANs to improve the translation process. It relies on the back-translation and evaluation steps to provide the necessary feedback for refining the translation.

Final Thoughts

The social approach to low-resource language translation provides a promising alternative to traditional methods. By imitating the roles and interactions of a human translation team, it offers a different perspective on how AI can be used for language translation tasks. As with any method, it has its strengths and challenges, but it adds another tool to the toolkit for tackling the complex problem of low-resource language translation.

Permalink →

#translation

First posted 2023-06-27

Language translation is a complex task, especially when it comes to ultra low-resource languages. Traditional methods may fall short in providing accurate translations due to limited data. However, swarm-based and hive-mind inspired approaches can offer novel ways to tackle this issue.

Swarm-Based Approach

Drawing from the principles of collective intelligence, the swarm-based approach involves multiple AI agents working together. Each agent is trained on different aspects or subsets of the language data. Key strategies in this approach include:

  • Dynamic Task Allocation: Agents dynamically choose tasks based on current system needs, similar to task distribution in a bee hive. This approach would require some mechanism for constantly tracking the state of the overall translation. If each component of the swarm is not just prompted but trained or fine tuned on a given state optimization task, then it would be possible to extrapolate from state optimization to new, unseen data.
  • Distributed Training and Voting: Each agent makes independent predictions based on its training. The final translation is determined by a majority vote or another consensus mechanism. I suspect this option is likely to work about as well as democracy does, so take that for what it’s worth, but let’s not completely rule it out.
  • Collaborative Learning: Agents learn from each other’s successes and failures to improve their performance. This one is probably the closest to the social approach to translation.
  • Stigmergy:
    • Stigmergy is how termite mounds get built and blood cells know what do to despite knowing nothing about the broader context or big picture. Each action leaves a small trace in the environment, providing the impetus for the next action, regardless of who or what accomplishes that subsequent action. In some ways, a stigmergy approach can be likened to a chess board: you don’t need to have tracked the entire development of the game in order to know what the next right move is. It might be better to think of stigmergy as people rotating through a large set of chess games, always making the next right move on each particular game based on the state of the chess board as they find it.
    • In the context of translation, an agents’ outputs can serve as inputs for others, creating a progressive chain of translation that evolves and improves over time. Envision each AI agent (i.e., an LLM leveraging something like the ReAct approach) detecting “environmental” patterns that trigger particular action patterns, while leaving a trace for further iterations by some agent.
    • One might deploy single agents to focus on particular phenomena (e.g., proper names, or processes, or entities, or circumstances, or direct discourse, etc.) in the text, with prompts tailored with the best grammatical and translation information available so far for each respective phenomenon. Aletrnately (or alongside these bots), an agent could be deployed for translating one specific word or phrase that occurs, armed with glosses for that word and all gold-standard example translations available that contain that word. Each bot would be thus empowered to gloss a word based on contextualized examples wherever it occurs in the source texts. This overall approach seems very promising to me.

Hive-Mind Inspired Approach

The hive-mind approach is inspired by the decentralized, coordinated functioning of a bee hive. Here, each agent starts with a base model, like GPT, which is then fine-tuned on a specific task or aspect of the language. The final translation is a combination of outputs from all agents.

Final Thoughts

Swarm-based and hive-mind approaches offer potential for more accurate translations for low-resource languages. However, they require sophisticated coordination mechanisms and could be more resource-intensive than centralized models. Nonetheless, in the quest for precision in language translation, these approaches open up exciting new possibilities.

Update 2023-08-18: I just heard about Sakana.ai, which is aiming to use a swarm-based approach to rival the capabilities of the largest transformer models.

Permalink →

A thought experiment. (credit to Ben Scholtens for asking the obvious question: Why not fork VS Code ourselves?)

2023-09-19 #ai #translation


Your Translation Project is a lot like a Software Project. Why not use a World-Class Text Editor?

🔍 The Insight: Bible translation, at its core, is a text-editing endeavor, akin in many ways to software development. It’s about collaborating, maintaining versions, and ensuring quality – just like developing a codebase.

❓ The Question: Why start from scratch when there’s a mature, battle-tested platform that offers vast capabilities tailored to these tasks?


VS Code: The Unsung Hero for Bible Translation

📖 No Loss in Functionality: At first glance, Paratext appears irreplaceable. But dive deeper, and you’ll find that the VS Code ecosystem can replicate its core functions, and it’s highly stable, scalable, and useable. From textual analysis, collaboration, to project management, there’s an extension for that. Oh, and it comes with rock solid AI integration.

🛠 Superior Toolset:

  • Stability & Text Editing: VS Code’s origin is text editing. Its advanced features ensure seamless, bug-free experiences.
  • Plug-ins: With tens of thousands of extensions, there’s a plugin for almost every need, and creating new ones is straightforward, whether you’re a software firm or an SIL programmer.
  • Git Integration: Mature version control is baked in, making collaboration and version tracking effortless.
  • File Management: Navigate complex projects with ease, and leverage the advanced file system capabilities.
  • LiveShare: Work on the same file across devices. Real-time collaboration made simple.
  • Customization: Connect to linting systems, render previews, automate tasks, and more.
  • Localization: Tailor the interface to your linguistic needs. It’s globally friendly.
  • Extensibility: VS Code’s architecture is primed for expansion, ensuring it’ll grow with your needs.
  • AI Integration: Benefit from native AI tools for smarter, quicker leveraging of all of your project resources and work to date.
  • Support & Documentation: A vast community, extensive documentation, forums, videos, and guides stand ready to assist.

The Implication:

While Bible translation has unique domain requirements, it shouldn’t reinvent the wheel for tasks common to many projects. By leveraging VS Code, we tap into a decade of optimization, a vast ecosystem, and avoid the pitfalls of building from the ground up. Imagine cutting down development time by 10 or 20 years (how long would it take a team to accomplish 115K commits, on thousands of branches, with as good a result as VS Code?), ensuring greater stability, and having a world-class UI — all while keeping focus on the unique needs of translation.

Some of the most advanced and complex features that translators or consultants could only dream of (like having complete project version control on an enterprise level with automated actions and quality check processes, or enabling 4 people in four geographic locations to collaborate on the exact same file in real time) are already built, tested, stable, and being used by hundreds of thousands of VS Code users.

Why would we put our time and effort into recreating all of this, when its already free and completely open source (MIT license)? In conclusion, the complexities of tool development are vast, but they’ve been met and tamed by VS Code. Rather than venturing into the wilderness to forge a new path, let’s stand on the shoulders of giants, repurpose what’s proven, and channel our energies solely into the specialized challenges of Bible translation.


🚀 The Call to Action: Before investing further in new tools, let’s explore the vast potential of VS Code. It promises a foundation that’s both solid and flexible, ensuring our Bible translation endeavors are as efficient, effective, and impactful as possible.


Minor update: VS Code fork seems feasible

Permalink →