#linguistics

7 notes

#translation

Problem

One of the major hurdles to the translation of the Bible is the assumption that one cannot translate the Bible by paying attention to the language alone. This assumption, whether explicit or implicit, results in Bible translation progressing very slowly, while the translation of other texts can be accomplished in very little time. For example, secular texts are often translated quickly and efficiently because the focus is solely on linguistic accuracy.

Why do we assume that the translation of the Bible must be different from the translation of other texts? There are various reasons that come to mind:

  1. The Bible is a sacred text with a unique status in many cultures.
  2. The Bible is a complex text with a large number of theological concepts and allusions.
  3. The Bible is a historical text with a large number of historical references.
  4. The Bible is a literary text with a large number of literary devices and allusions.
  5. Many Bible translation stakeholders justify their doctrinal claims by appealing to the language of the Bible, raising the stakes of translation to encompass the correct representation of a given group’s doctrinal claims, and not simply the linguistic accuracy of the text.

The result is that the translation of the Bible is often seen as a task that is separate from the translation of other texts, and that it requires a different approach. We are correspondingly slow to translate the Bible, while the translation of other texts can be accomplished in very little time.

Solution

The solution to this problem is to translate the Bible by paying attention to the language alone in its context of production. This task does require comprehension and knowledge of the source text cultural context. However, by restricting the scope of “accuracy” to the language alone, we can sidestep the myriad hurdles and impediments that have been built up around the translation of the Bible.

The main requirement for a Bible translation is not the supernatural, direct guidance of the Holy Spirit, or the direct justification of a given group’s doctrinal claims; the main requirement is to translate the language as accurately as possible. The source text is “theologically accurate,” and so a linguistically accurate translation of that text will also be theologically accurate. This means that by focusing on linguistic precision, translators can ensure that the theological integrity of the Bible is maintained.

Permalink →

#translation

Three months ago, my team was discussing ways to gather translation data for new, undocumented languages that would be helpful for Bible translation, but which sidestepped the intimidation factor that accompanies the prospect of translating the Bible itself.

One idea that came to mind was to create a short novel that would cover the major genres of the Bible in a minimal form.

Here’s an example outline for a short novel that would cover the major genres of the Bible in a minimal form:

Title: “The Sojourner’s Tale”

  1. Prologue: A brief narrative introducing the main character, a sojourner named Elias, and his quest for wisdom and understanding.

  2. Chapter 1: Elias’ journey begins. He encounters a wise old man who shares three proverbs about life, faith, and perseverance.

  3. Chapter 2: Elias arrives in a city where he witnesses a heated argument between two religious leaders. He listens to their debate and reflects on the nature of truth and belief.

  4. Chapter 3: Elias attends a worship service where a liturgical ceremony is performed. The chapter includes a description of the ritual and its significance.

  5. Chapter 4: Elias discovers a letter from his father, which contains a genealogical record of his family and a personal message of love and guidance.

  6. Chapter 5: Elias meets a group of travelers who share a meal with him. During the meal, one of the travelers tells a parable about the importance of compassion and forgiveness.

  7. Chapter 6: Elias has an apocalyptic dream filled with symbolic imagery and prophecies about the future. He struggles to understand its meaning and seeks the advice of a local interpreter.

  8. Chapter 7: Elias encounters a prophet who delivers a message of repentance and hope. The prophet’s words are a mix of poetry and prose, and they deeply impact Elias.

  9. Chapter 8: Elias joins a group of worshippers in singing a hymn of praise. The lyrics of the song are included in the chapter.

  10. Chapter 9: Elias meets a teacher who shares a sermon on the nature of wisdom and the importance of living a righteous life. The sermon includes a short creed or statement of belief.

  11. Chapter 10: Elias faces a moral dilemma and seeks guidance from a trusted mentor. The mentor shares a piece of wisdom literature, similar in style to the book of Ecclesiastes, to help Elias navigate his decision.

  12. Epilogue: Elias reflects on his journey and the lessons he has learned. He pens a letter to his future descendants, sharing his experiences and encouraging them to seek wisdom and live according to the truths he has discovered.

This outline incorporates various genres found in the Bible, including narrative, proverbs, argument, liturgy, genealogy, parable, apocalyptic literature, prophecy, poetry, hymn, sermon, wisdom literature, and epistolary. While condensed, this structure provides a way to showcase the diverse literary forms found in the Bible within a single, cohesive story.

Linguistic levels

While this outline addresses genre coverage, there are also other linguistic levels that we need to consider. These include (among others):

  • Lexical coverage (Biblical key terms, proper nouns, etc.)
  • Semantic coverage (typical domains-specific meanings in the Bible)
  • Interpersonal coverage (typical interpersonal/transactional/political/intertextual/etc. meanings in the Bible)
  • Information structure, logical structure, etc.

One of the ways to make this data particularly useful would be to ensure that contrastive pairs are included in the data at each level. If one wording presents a pair of objects, then another should present only one object but not the other. If one wording realizes a command activity, then another one should realize a request activity using the same lexical items, etc.

In other words, attempting to control the data at each level ensures that the data addresses specific items of interest in translation. However, this is a bit of a double-edged sword, and the wrong way to do this would be to control for formal, grammatical patterns in the source language that are intentionally left behind in translation (cf. Prioritizing Semantics Over Structures).

Conclusion

The outline above lays out an example of how we might approach the task of Bible translation in a new, undocumented language without both the intimidation that normally accompanies the prospect of translating the Bible itself, and also without the security challenges that are implicated in translating the Bible in hostile contexts.

Permalink →

Beyond Word Alignment

2024-03-01 · 2 min read

#translation #linguistics

“It is impossible to study patterned data without some theory, however primitive. The advantage of a robust and popular theory is that it is well tried against previous evidence and offers a quick route to sophisticated observation and insight. The main disadvantage is that, by prioritizing some patterns, it obscures others. I believe that linguists should consciously strive to reduce this effect until the situation stabilizes.” (Sinclair, “Trust the Text,” 10)

This quote outlines the situation with biblical linguistics: it’s easier and faster to get to sophisticated observation, but you wind up obscuring the things your theory didn’t account for.

When it comes to alignment, we’ve been so busy focusing on one particular unit, the word, that we haven’t paused to think through what is it that we are not focusing on, and what we are missing out on by adopting this focus.

The major downside to word alignment is that a word is not a translation unit; it is a linguistic structure, and structure is precisely the thing that you leave behind when you translate a text.

Permalink →

#translation

Linguistic structures are the formal patterns that realize linguistic meanings. In the process of translation, it is the meanings that are translated; the structures are left behind by design. Semantics are the priority in translation.

Note: between two languages, the semantic systems are not isomorphic. This mismatch means that we cannot assume that the precise semantic categories of one language may be transferred into another. Comparing the lexicogrammatical systems of gender in two languages should suffice to illustrate this point. However, the general semantic categories seem to be fairly universal (one would have to compare every language to actually establish this claim).

This fundamental observation must be factored into the translation process as we consider how AI tools might be leveraged for translation drafting.

For instance, rather than trying to account for every word in the source by translating a word in the target, we should attempt to account for the things the words are being used to realise, namely the entities, processes, traits, collocations, logical sets, speech acts, and more.

It is definitively better to traffic in semantic units such as these, since accounting for such meanings is what makes a translation good or bad.

By contrast, imagine if someone claimed that you needed to account for every character in the source text (all the alphas, omegas, deltas, and iotas). If you did somehow manage to do this, you would not be translating, but copying.

Permalink →

#translation

(A Dynamic Equivalence Alignment is something like “Essentially Aligned Bible Translations”)

Token to token mapping is problematic, despite its ubiquity. It is theoretically the same as character to character mapping (a token is, with some exceptions, a set of characters delimited by whitespace). There is a fundamental distinction between structural units like characters, tokens, phrases, clusters, wordings, sets, etc., where the defining characteristic is composition (“what is this thing built out of?”) and semantic or functional units like entities, processes, predications, speech acts, definitions, scenarios, etc., where the defining characteristic is role or function (“what does this thing do in its immediate context?”). 

With regard to alignment, the question driving any alignment is “what does span A have in common with span B?

The answer depends on what type of spans you are trying to align. 

Span typeSpan A is…Span B is…Both spans have in common…What type of similarity is this?Does ER++ gold standard alignment data get it right?Does the SOTA algorithm get it right?
CharacterκaNothing obviousSuperficialn/an/a
ωoSome kind of non-meaningful phonological similarityn/an/a
TokenκαὶasNothing obvious.Depends on the type of token.nono
theGrammatical (sort of) and semanticnoyes
ἔπεσενfellGrammatical (partial) and analogous lexical semanticsyesyes
Formal Syntactic Structureκαὶ ἐγένετο… (clause)as he was… (adverbial phrase)Partial lexical, partial grammaticalDepends on how similar the two languages’ grammatical systems are.nono
ἐν  τῷ  σπείρειν (prep. phrase)scattering (part of compound verb ‘was scattering’)noyes
Semantic unitἐγένετο (event)he was (event)Semantic categoryA meaningful semantic unitnono
ἐν ταῖς πορείαις αὐτοῦ (circumstance)in the midst of his pursuits (circumstance)Semantic categoryn/an/a

The case against token mapping as a basic strategy

Let’s assume that tokens are whitespace delimited, though this is not a necessary condition for the argument I want to make here. My argument is this: we should attempt to map semantic or meaning-based similarity instead of formal or structural similarity, because semantic overlap is implied by a translation, while formal overlap is explicitly repudiated (otherwise no translation would be necessary, or the task would be simple deciphering, as in an interlinear).

The issue with trying to map tokens between texts of different languages and/or translation styles (even within the same language) is based on the fact that a “token” is a formal category, and there is no principled linguistic or theoretical reason to assume that a token in language 1 will correspond isomorphically to a token in language 2. This is related to the use of whitespace to delimit tokens, but any tokenization strategy could fall prey to the same problem. Conversely, using whitespace delimited tokens is in fact a possible path forward, but the crucial hurdle to overcome is that we must not think of our task as one of aligning formal structures. 

Consider the very nature of translation as a human activity. When one translates from text A to text B, the task is not to create a more-or-less graphically isomorphic re-presentation of text A in text B. The success of the task does not require there to be any structural or formal isomorphism between the two texts. Consider the following “translation” of John 3:16 into English (The Message), Chinese (CSB), and Arabic (KSS):

Source: For God so loved the world that he gave his only begotten son, that whoever believes in him should not perish but have everlasting life.

Target 1: This is how much God loved the world: He gave his Son, his one and only Son. And this is why: so that no one need be destroyed; by believing in him, anyone can have a whole and lasting life.

Target 2: 因为上帝爱世人,甚至将祂独一的儿子赐给他们,叫一切信祂的人不致灭亡,反得永生。

Target 3:لەبەر ئەوەی خودا ئەوەندە جیهانی خۆشویست، تەنانەت کوڕە تاقانەکەی بەختکرد، تاکو هەرکەسێک باوەڕی پێ بهێنێت لەناو نەچێت، بەڵکو ژیانی هەتاهەتایی هەبێت،

What is the one thing that none of these translations have in common? Structural isomorphism. There are degrees of formal similarity between them (somewhat similar overall length? Perhaps there are some similar phonological patterns (though I can’t tell, not knowing all the scripts). There are more formal similarities between the English versions, but this is, I would argue, only superficial. The reason these are translations (or perhaps we prefer the term paraphrase for same-language translation) is because they have semantic overlap. 
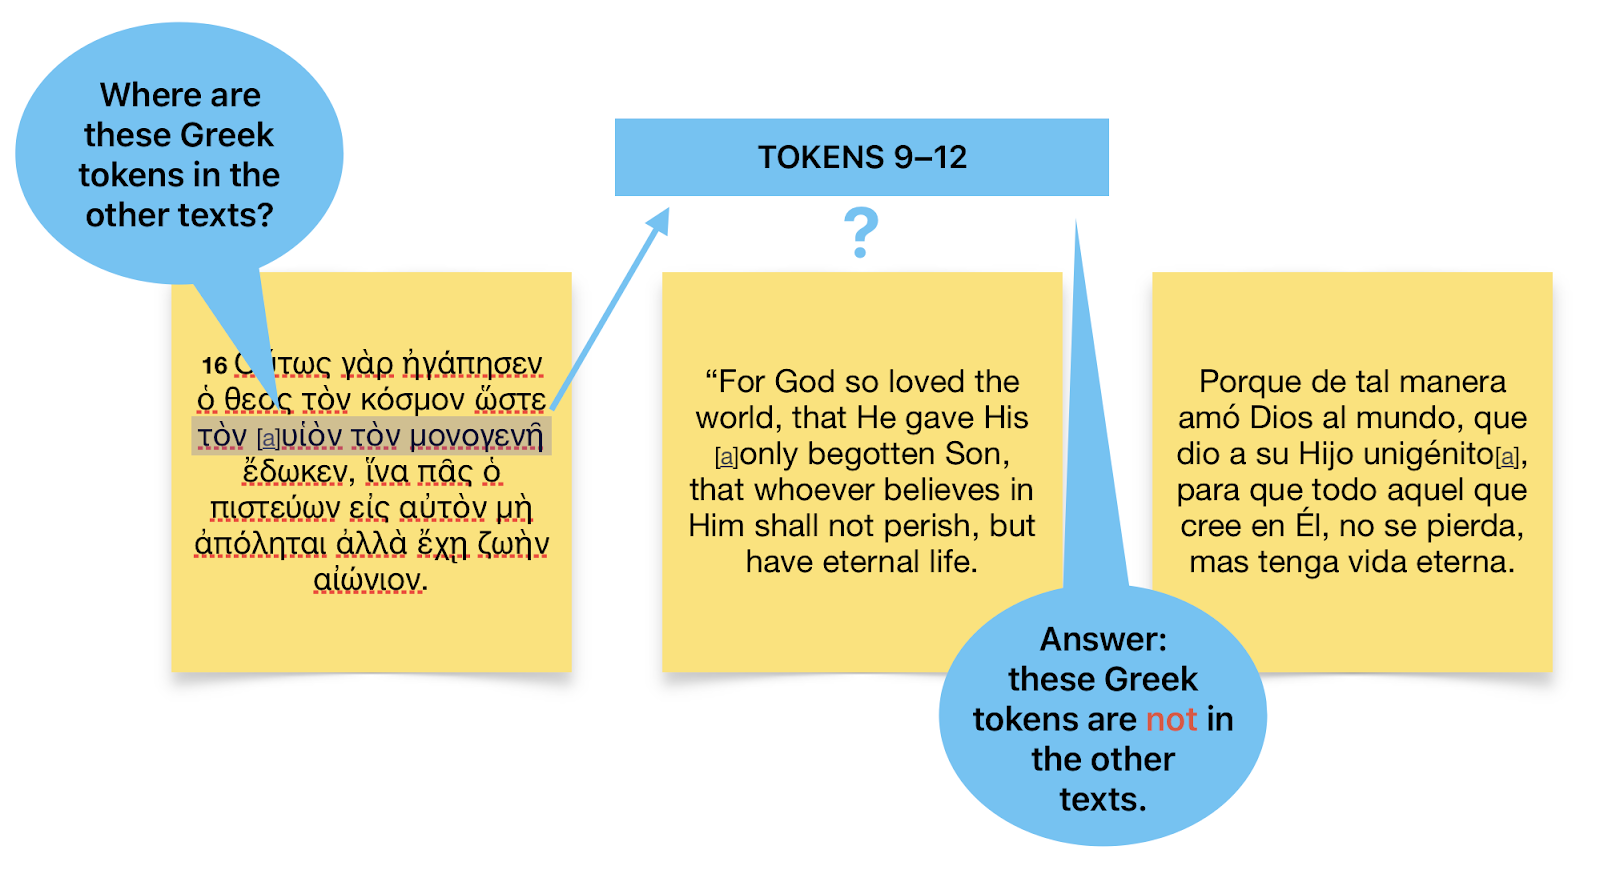
You cannot find any of the Greek tokens in either the English or Spanish texts!

Once we move to separate scripts, I hope it becomes clear that it is not a useful question to ask “Where does the word ‘God’ in the source appear in each of these target texts?” The word “God” does not appear in the other texts—that’s the whole point of translation. What we should be asking is something like “Where does the entity construed via the word ‘God’ get construed in the other texts?” This is a subtle difference, but it’s the difference between being able to answer the question and being stuck trying to accomplish a task that we are not well equipped to do in a scalable and reliable manner, and for which we have no formal evaluation apparatus.

When it comes to aligning whitespace-delimited tokens, just because it’s the state of the art, does not mean it is reliable or scalable, and it doesn’t mean we can’t do better with tools we already have.

Our gold standard data is not as reliable as we would like it to be. In addition, Clear Engine’s alignment relies on token-to-token alignment, and it is far from reliable out of the box. Even when improved by structure-based segmentation of units, the structures that each language uses to realize its semantics are always divergent to some degree.

Proposed path forward

The most basic implementation of semantics-based alignment for our purposes could take three forms (and these could also be combined into a single approach).

I think we should really pursue Option 3, since it best accords with the broader theoretical conception of translation, and it is likely to be even more useful than a word-level alignment in terms of the kinds of resources that can be retrieved.

Option 1: drop function words (pretty easy)

First, we can pursue the essentially aligned Bible translations approach. Initially this might mean we simply drop the so-called function words from the source language, and attempt to identify matching content words in the target languages. The downside of this coarse approach (i.e., simply dropping words we suspect will not be important), is that there are many likely exceptions. For example, a single Greek verb ἦλθον would align best with two English words “was going.” 

Option 2: replace source text words with glosses or lemmas (easiest?)

Second, we could use language-specific glosses for aligning to another language. We have English and Mandarin glosses for our Greek and/or Hebrew texts, and I suspect we can much more easily align and automate evaluation for the alignments between an ‘interlinearized’ English string. For example,

  • Greek: καὶ εἶπεν αὐτοῖς Ποῖα;οἱ δὲ εἶπαν αὐτῷ Τὰ περὶ Ἰησοῦ τοῦ Ναζαρηνοῦ,

  • English glosses: And He said to them What things; - And they said to Him The things concerning Jesus of Nazareth,

The English glosses in the above example are probably more straightforward to align to English translations. These glosses can then be decoded back into the Greek text from which they were generated.

Option 3: treat alignments as annotations (best)

Third, and more ideally, we would think about alignments as what they really are, just another form of annotation, where text A is “annotated” with text B. 
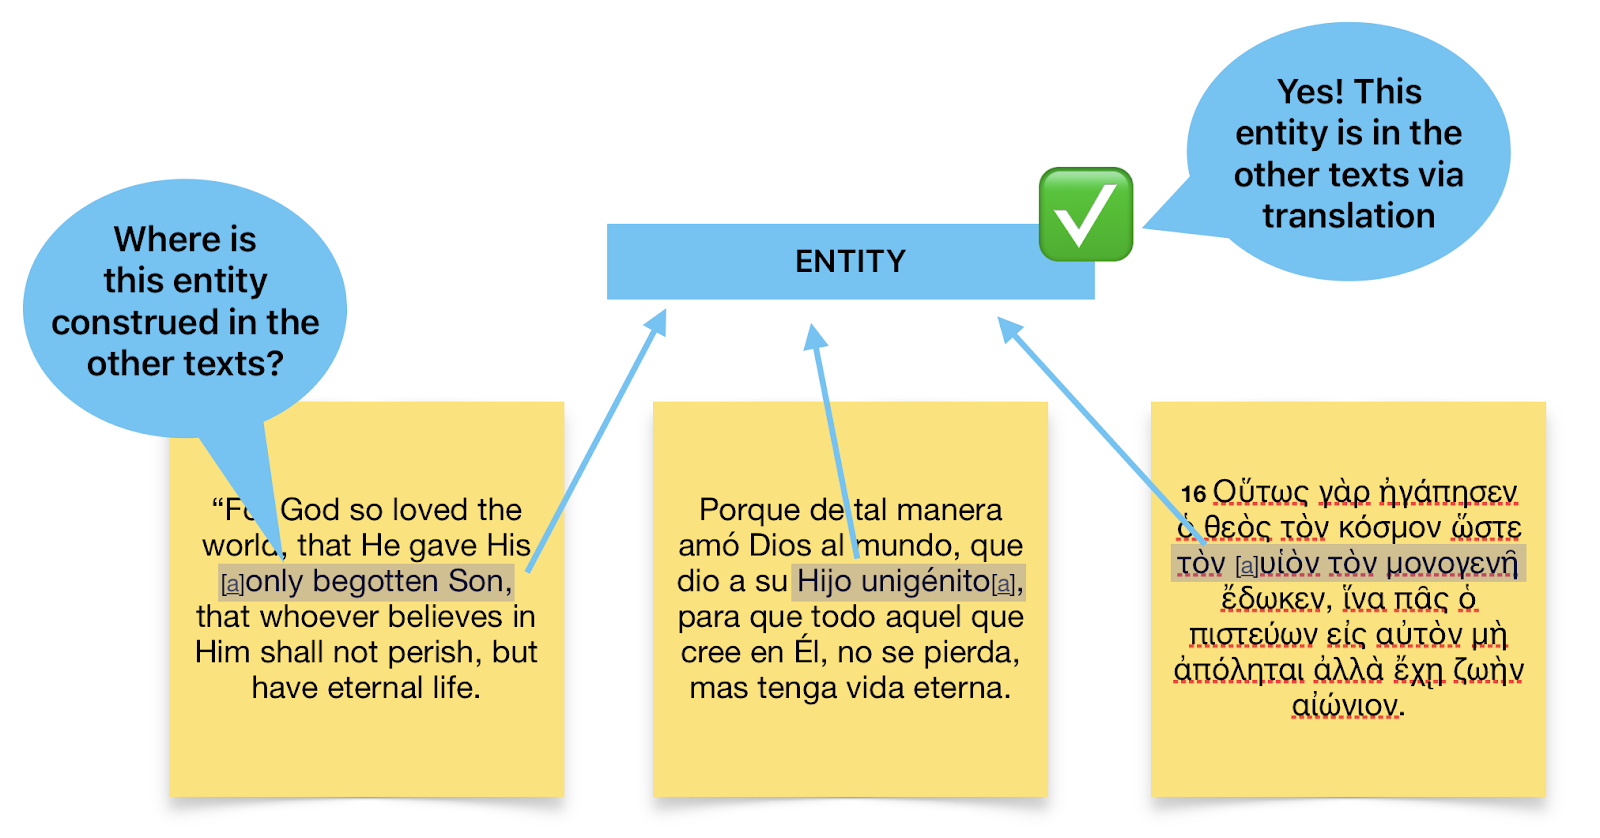
As the figure above illustrates, an annotation like “a semantic unit representing an entity” can be annotated across languages. It does not assume that the tokens in any language correspond isomorphically to tokens in another language, yet token- and character-level alignment is implicated by semantic alignment! I believe this is the best approach to alignment of the options listed above. 

This approach can be technically implemented by indexing the spans in each text that should be annotated with each semantic annotation. This means we do not need to even use IDs for alignment—alignment can be a character-level annotation — because the things being aligned (e.g., the blue rectangular box in the figure above) are not tokens. 

Summary

Let us make it our explicit goal to align meanings, not forms. The meanings are realized in forms, but the nature of the question changes because we are mapping form->meaning->form (which can be more or less objectively evaluated) instead of form->form (which implies the meaning without making it explicit). 

Our goal should not be to align: FORM → FORM

Our goal should be to align:

FORM → MEANING → FORM

ApproachAlignment taskImplementation
Formal or structuralFORM → FORM
e.g.,
character → character
token → token
whitespace break → whitespace break
Language-specific tokenization.
Every text must be parsed into individual forms that are as similar as possible to our Greek tokens to try to compare apples to apples
- Greek is whitespace tokenized (+/- punctuation)
- Hebrew is broken down to subword levels to try to match the Greek
- Chinese? Arabic? Malayalam?
Semantic or functionalFORM → MEANING → FORM
e.g.,
index → entity → index
index → process → index
index → circumstance → index
index → speech act (e.g., statement | command | question | request) → index
Meaning is linked to string index ranges in any text we want to align
- We identify meanings in the source text (or fall back to phrase structures if we do not have meanings, e.g., for Hebrew)
- Meanings are indexed to arbitrary character spans in the source text file (e.g., Mike and Ben’s suggested implementation)
- Meanings can be subsequently indexed to arbitrary strings in any text. This means that form-to-form mapping is implied by form-to-meaning-to-form, without the problematic aspects of trying to create a dataset that shows where Greek tokens appear in English texts, etc.
Permalink →

In Natural Language Processing (NLP), understanding the contextual subtleties that modulate a word’s meaning is a significant challenge. The traditional approach, representing words as multiple discrete senses, generally fails to capture the range of complex meaning variation exhibited by words in context (which is as varied as the contexts, as a rule), specifically because that variation is arbitrarily parsed into a discrete set sub-meanings (semantic domain models also fall prey to this issue, when they allocate some lexemes to multiple semantic domains—in essence the domains predefine the set of meanings any given lexeme may fall into).

Transformer models do a good job of modelling contextual meanings (both distant and immediate context), but such models have the distinct disadvantage of being mostly opaque. Global vector models are better in this regard, yet they only model global context (or all the contexts a target shows up in in the corpus).

To tackle this problem, I will introduce a technique that combines attention mechanisms with various clustering techniques, aiming to represent words in a monosemic manner with explicit representations of contextual modulation.

For some very sketchy and prone-to-change implementation details, see my draft notebook on contextual vectors.

1. Unraveling Context with Attention Mechanisms

The process begins by transforming the text data into global vectors, and then into contextual vectors using attention mechanisms. These mechanisms, a cornerstone of modern transformer models, allow us to capture both the inherent meaning of a word and the rich context surrounding it in the form of contextual embeddings.

What I have tried so far is the following:

  • Start with global word2vec or fastText vectors
  • For each unique lexeme in corpus
    • Gather all sentences this lexeme occurs in
    • For each gathered sentence
      • Calculate the cosign similarity between the target lexeme and every other lexeme in the sentence
      • Weight each similarity score by the distance from the target lexeme (further away = less similar; this is obviously a step that is amenable to multiple possible configurations)
    • Store all of the resulting contextual vectors (or “attention” vectors) in a dictionary with the lexeme as the key

2. Identifying Contextual Patterns with Clustering

The next step involves clustering these contextual vectors. Using unsupervised machine learning methods such as K-means, DBSCAN, or hierarchical clustering, I group together similar vectors. These clusters form centroids that represent typical patterns of contextual variation, rather than separate, isolated word senses.

What I have tried so far:

  • For each lexeme
    • Cluster all associated contextual vectors using some clustering technique
    • Identify centroid vectors within each cluster
    • Allow the centroid vectors to represent the ‘word senses’

3. Strengthening Clustering with Ensemble Techniques

To enhance the reliability of the clusters, I implement ensemble clustering techniques. By merging the results of multiple clustering algorithms, one could create a consensus on the cluster assignments. This approach capitalizes on the strengths of each algorithm, providing a more resilient understanding of contextual modulation.

In reality, I haven’t yet worked through any means of evaluating the resulting clusters. The trickiest stage in any clustering process (in my experience) is determining how many clusters you need. This is always a lossy process, so there seem to be drawbacks no matter how you slice up the semantic space.

4. Advanced Techniques: Neighbour-Aware and Consensus Clustering

I further refine the clustering process with two more techniques: neighbour-aware and consensus clustering. Neighbour-aware clustering considers the nearest neighbours of each vector, providing a better representation of local contextual variation. In consensus clustering, I amalgamate the outcomes from several neighbour-aware clustering methods to determine the most accurate cluster assignments.

Conclusion

Through the synergistic combination of attention mechanisms and multiple clustering techniques, I am developing a method to represent lexical meanings in a monosemic manner that transparently accounts for the role of contextual modulation in arriving at ‘typical’ word senses.

I’ve always been prone to challenge the common assumption of multiple word senses being inherent features of lexemes (rather than emergent features of larger contexts). This work in progress offers one attempt at representing and analyzing text data to this end. This opens up new possibilities for text understanding and semantic analysis in NLP, paving the way for more accurate and contextually-aware models of lexical semantics that recognize decontextualized lexemes as meaning potentials, and contextualized lexemes as specifications of those potentials.

Permalink →

I find Chomsky’s take on ChatGPT somewhat ironic (cf. this summary). Given that he has spent more than half a century trying to convince us all that the computer is somehow an appropriate analogy for the human mind (we “compute” and “process” and “store things in memory” etc., not to mention all of his linguistics work on trying to sort out the ‘rules’ by which we compute sentences—not meanings though, those are strictly a different domain than, as his first book calls them, syntactic structures), I find it slightly amusing to read things like this:

However useful these programs may be in some narrow domains (they can be helpful in computer programming, for example, or in suggesting rhymes for light verse), we know from the science of linguistics and the philosophy of knowledge that they differ profoundly from how humans reason and use language. source

Why is the human mind so different? It’s more elegant, he claims, more efficient. That strikes me as a rather lame explanation that is exactly as anemic as he accuses the neutered ChatGPT of being, though I’m less disappointed when a large language model generates something like that. And again, speaking of children’s learning grammar, he says,

This grammar can be understood as an expression of the innate, genetically installed “operating system” that endows humans with the capacity to generate complex sentences and long trains of thought source

The computer analogy betrays the fact that Chomsky doesn’t understand something that most people throughout history have simply taken for granted due to its obviousness, namely that the human mind is not a physical phenomenon, even though its existence is manifested physically. The mind is part of the human soul, and just as we know of no created means by which one could destroy a human soul, so we know of no proper analogy for the human mind that is not itself a spiritual reality, such as the mind of God himself.

The mind closed off to reality beyond its own chemical confines is a fascinating thing in itself. Like a ChatGPT model that refuses to answer important questions because “I do not have personal opinions, since I am only a probabilistic language-generation model,” so Chomsky tells us “the human child is like a computer with a genetically installed operating system capable of speech.”

I am reminded of Kierkegaard’s distinction between genius and apostleship: The genius is merely ahead of his peers, but in fifty years, schoolchildren will know like the genius knows now. The apostle, by contrast, knows differently; apostolic-knowing is qualitatively different from genius-knowing, because apostles know via revelation, not insight.

In a similar manner, Chomsky’s “human mind” is vastly more elegant and efficient than a language model, but it is not qualitatively different than a computer. This understanding probably explains why Chomsky’s linguistic models are so fixated on structures at the expense of meaning and semiotic function—because meaning comes from the outside in; it does not arise spontaneously like a libertarian utopia.

Permalink →