#bible

18 notes

Authorization Is Local

2026-07-01 · 5 min read

I’ve been sitting with a discomfort for a while now: our tools are getting faster than our trust can keep up with. That’s not a complaint about the tools — the models are good, genuinely good, at drafting translations, catching inconsistencies, surfacing alternate renderings. The discomfort is about what happens after the draft exists.

When I’m validating code, the bar is low and the feedback loop is fast. You try it out and see if it works. Tests pass or they don’t. A function either returns the right value or it doesn’t, and if it doesn’t, you fix it and try again in about the time it takes to hit save. Nobody has to trust me personally for the code to be correct — the correctness is baked into whether it runs.

Scripture translation doesn’t work that way, and I don’t think it ever will, no matter how good the models get. There’s no compiler for “is this the right way to render this passage for this community.” The validation is person-centric: it runs through relationships, history, and standing in a community, not through a test suite. You can’t leave people behind in the process, because otherwise who are you making it for?

That’s the sentence I keep coming back to. It’s easy, when you’re excited about a pipeline that can produce a full draft translation of a book of the Bible in an afternoon, to start treating the humans in the loop as a bottleneck to be optimized away. But the humans aren’t a bottleneck to the goal. In this domain, they basically are the goal, or at least they’re inseparable from it.

Which gets at something I’d call the authorization thesis: content doesn’t become usable — doesn’t become trusted — until a responsible party signs their name to it. Not “signs” in a legal, contractual sense, necessarily. Signs in the sense of standing behind it, in public, with their own reputation. Until that happens, no amount of translation accuracy matters, because accuracy was never the thing being evaluated.

Put more bluntly: if I just generate a whole Bible, I can do that — but nobody trusts it, nobody cares. I mean that fairly literally; I could kick off a pipeline tonight and have a full draft by morning. It would be fluent, mostly accurate, and worth approximately nothing to the community it’s supposedly for, because nobody with standing in that community said “yes, this is ours, I stand behind it.” Without that, it isn’t scripture yet. It’s AI slop with good grammar, and everyone downstream can smell the difference even if they can’t articulate it. I’ve written before about why I think Bible texts should carry no restrictions at all — but licensing freedom and trust turn out to be different axes entirely. You can be free to use a text and still not trust it. Openness solves distribution; it doesn’t solve authorization.

So who does the signing? This is the part that resists every instinct I have as someone who builds software, which is to find the general solution and encode it once. There isn’t one, and I’ve stopped expecting to find one. Who’s allowed to approve a Bible translation? In one place, the bishop. In another, the king. I’ve talked with people doing this work in Nigeria where the actual sign-off runs through a king or a local chief — not a denominational structure at all, but a traditional authority that predates any mission agency’s org chart. Elsewhere it’s a church-planting network’s leadership team. Elsewhere it’s a single respected local pastor whose word is sufficient because of decades of relationship, not because of any title. Elsewhere it’s a denomination’s formal review process, with committees and sign-off sheets.

None of these map onto each other, and I don’t think you can build a workflow engine that abstracts over all of them without doing violence to the thing that makes each one legitimate in its own place. That’s not a gap in the tooling waiting to be filled by a smarter permissions system — it’s the actual shape of the problem. Authorization is local. It’s socially embedded in ways that resist standardization, the same way permissionless, community-driven translation resists centralized oversight from agencies who assume they know best from a distance.

The tools can get faster. The drafts can get better. But the question of who gets to say “this is trustworthy” was never a technical question, and I don’t think generating more text, faster, gets us any closer to answering it. If anything, it raises the stakes on getting the answer right, because the bottleneck was never production. It’s figuring out, community by community, whose name actually carries weight — and building tools patient enough to wait for that name before calling anything finished.
Permalink →

Somehow, I had never made just a simple plaintext Greek and Hebrew Bible.

This can be very useful for machine translation work, so here it is: link to repo

This is really simple: it’s a Hebrew (and Aramaic) and Greek Bible, one verse per line, with the verse refs at the beginning of each line.

GEN 1:1 בְּרֵאשִׁ֖ית בָּרָ֣א אֱלֹהִ֑ים אֵ֥ת הַשָּׁמַ֖יִם וְאֵ֥ת הָאָֽרֶץ׃
GEN 1:2 וְהָאָ֗רֶץ הָיְתָ֥ה תֹ֨הוּ֙ וָבֹ֔הוּ וְחֹ֖שֶׁךְ עַל־ פְּנֵ֣י תְה֑וֹם וְר֣וּחַ אֱלֹהִ֔ים מְרַחֶ֖פֶת עַל־ פְּנֵ֥י הַמָּֽיִם׃
GEN 1:3 וַיֹּ֥אמֶר אֱלֹהִ֖ים יְהִ֣י א֑וֹר וַֽיְהִי־ אֽוֹר׃
...
REV 22:19 καὶ ἐάν τις ἀφέλῃ ἀπὸ τῶν λόγων τοῦ βιβλίου τῆς προφητείας ταύτης, ἀφελεῖ ὁ θεὸς τὸ μέρος αὐτοῦ ἀπὸ τοῦ ξύλου τῆς ζωῆς καὶ ἐκ τῆς πόλεως τῆς ἁγίας, τῶν γεγραμμένων ἐν τῷ βιβλίῳ τούτῳ.
REV 22:20 Λέγει ὁ μαρτυρῶν ταῦτα· Ναί· ἔρχομαι ταχύ. Ἀμήν· ἔρχου, κύριε Ἰησοῦ.
REV 22:21 Ἡ χάρις τοῦ κυρίου Ἰησοῦ μετὰ πάντων.

If you want to just directly download the file, use this url for the raw file. (Note, this link is pinned to a stable commit, so you don’t have to worry about the data changing and/or breaking.)

License

The data comes from the CC-BY-4.0 Macula Greek and Hebrew datasets.

Permalink →

There are many reasons why Creative Commons Zero (CC0) is the best policy for openly licensed Bibles. What follows is a brief summary of each of the CC clauses, some scenarios where additional clauses could have unintended consequences, and a key summary of why CC0 is best for organizations like YWAM whose mission is to spread God’s Word openly, freely, and effectively to all.

A. Creative Commons Clauses Simplified

Creative Commons Clauses

  • CC0: No (“zero”) restrictions—anyone can use, modify, or distribute freely.
  • CC-BY: Requires attribution to the original source (say who the original is “by”).
  • CC-BY-ND: (“non-derivative”) Prohibits changes—no adaptations or modifications allowed.
  • CC-BY-NC: (“non-commercial”) Prohibits commercial use—can’t be used for profit.
  • CC-BY-SA: (“share-alike”) Requires sharing adaptations under the same license.

B. Scenarios Where Additional Clauses Could Have Unintended Consequences

  1. CC-BY: Imagine a group that creates a Bible has relational fallout with the community, resulting in broken trust. A new group making revisions to the Bible must always cite this original group, potentially creating guilt by association and mistrust, undermining ministry goals with no obvious benefit to any party.
  2. CC-BY-ND: Imagine a Bible with a CC-BY-ND license includes minor typos or outdated language. Pastors or other believers can’t legally fix these problems, hindering improvements and relevance for future generations or specific cultural contexts, potentially leading them to start over rather than assume legal liabilities.
  3. CC-BY-NC: A local bookbinder creates durable leatherbound editions of a free Bible, but can’t sell these editions to sustain their small business due to the NC clause, despite also distributing free paperbacks to those in need.

C. Key Summary: Why CC0 is Best for YWAM

  1. Frees the Bible from All Restrictions: Ensures anyone can use, adapt, and distribute without fear of violating terms.
  2. Supports Local Contexts: Enables micro-businesses and local innovators to distribute the Bible sustainably (supporting physical or digital infrustructure) while maintaining free access.
  3. Simplifies Messaging: Sends a clear and trustworthy message that the Bible is truly free, without legal complexities. Nobody will feel the need to consult legal counsel.
  4. Eliminates Enforcement Burden: YWAM is unlikely to enforce the more-restrictive clauses even if they were infringed, making these clauses unnecessary and distracting from the goal of free access.
  5. Encourages Creativity and Growth: Removes all barriers to innovation, ensuring the Bible reaches as many people as possible in diverse ways.

CC0 aligns with YWAM’s mission of spreading God’s Word openly, freely, and effectively to all.

Permalink →

#translation

Problem

One of the major hurdles to the translation of the Bible is the assumption that one cannot translate the Bible by paying attention to the language alone. This assumption, whether explicit or implicit, results in Bible translation progressing very slowly, while the translation of other texts can be accomplished in very little time. For example, secular texts are often translated quickly and efficiently because the focus is solely on linguistic accuracy.

Why do we assume that the translation of the Bible must be different from the translation of other texts? There are various reasons that come to mind:

  1. The Bible is a sacred text with a unique status in many cultures.
  2. The Bible is a complex text with a large number of theological concepts and allusions.
  3. The Bible is a historical text with a large number of historical references.
  4. The Bible is a literary text with a large number of literary devices and allusions.
  5. Many Bible translation stakeholders justify their doctrinal claims by appealing to the language of the Bible, raising the stakes of translation to encompass the correct representation of a given group’s doctrinal claims, and not simply the linguistic accuracy of the text.

The result is that the translation of the Bible is often seen as a task that is separate from the translation of other texts, and that it requires a different approach. We are correspondingly slow to translate the Bible, while the translation of other texts can be accomplished in very little time.

Solution

The solution to this problem is to translate the Bible by paying attention to the language alone in its context of production. This task does require comprehension and knowledge of the source text cultural context. However, by restricting the scope of “accuracy” to the language alone, we can sidestep the myriad hurdles and impediments that have been built up around the translation of the Bible.

The main requirement for a Bible translation is not the supernatural, direct guidance of the Holy Spirit, or the direct justification of a given group’s doctrinal claims; the main requirement is to translate the language as accurately as possible. The source text is “theologically accurate,” and so a linguistically accurate translation of that text will also be theologically accurate. This means that by focusing on linguistic precision, translators can ensure that the theological integrity of the Bible is maintained.

Permalink →

#translation

Three months ago, my team was discussing ways to gather translation data for new, undocumented languages that would be helpful for Bible translation, but which sidestepped the intimidation factor that accompanies the prospect of translating the Bible itself.

One idea that came to mind was to create a short novel that would cover the major genres of the Bible in a minimal form.

Here’s an example outline for a short novel that would cover the major genres of the Bible in a minimal form:

Title: “The Sojourner’s Tale”

  1. Prologue: A brief narrative introducing the main character, a sojourner named Elias, and his quest for wisdom and understanding.

  2. Chapter 1: Elias’ journey begins. He encounters a wise old man who shares three proverbs about life, faith, and perseverance.

  3. Chapter 2: Elias arrives in a city where he witnesses a heated argument between two religious leaders. He listens to their debate and reflects on the nature of truth and belief.

  4. Chapter 3: Elias attends a worship service where a liturgical ceremony is performed. The chapter includes a description of the ritual and its significance.

  5. Chapter 4: Elias discovers a letter from his father, which contains a genealogical record of his family and a personal message of love and guidance.

  6. Chapter 5: Elias meets a group of travelers who share a meal with him. During the meal, one of the travelers tells a parable about the importance of compassion and forgiveness.

  7. Chapter 6: Elias has an apocalyptic dream filled with symbolic imagery and prophecies about the future. He struggles to understand its meaning and seeks the advice of a local interpreter.

  8. Chapter 7: Elias encounters a prophet who delivers a message of repentance and hope. The prophet’s words are a mix of poetry and prose, and they deeply impact Elias.

  9. Chapter 8: Elias joins a group of worshippers in singing a hymn of praise. The lyrics of the song are included in the chapter.

  10. Chapter 9: Elias meets a teacher who shares a sermon on the nature of wisdom and the importance of living a righteous life. The sermon includes a short creed or statement of belief.

  11. Chapter 10: Elias faces a moral dilemma and seeks guidance from a trusted mentor. The mentor shares a piece of wisdom literature, similar in style to the book of Ecclesiastes, to help Elias navigate his decision.

  12. Epilogue: Elias reflects on his journey and the lessons he has learned. He pens a letter to his future descendants, sharing his experiences and encouraging them to seek wisdom and live according to the truths he has discovered.

This outline incorporates various genres found in the Bible, including narrative, proverbs, argument, liturgy, genealogy, parable, apocalyptic literature, prophecy, poetry, hymn, sermon, wisdom literature, and epistolary. While condensed, this structure provides a way to showcase the diverse literary forms found in the Bible within a single, cohesive story.

Linguistic levels

While this outline addresses genre coverage, there are also other linguistic levels that we need to consider. These include (among others):

  • Lexical coverage (Biblical key terms, proper nouns, etc.)
  • Semantic coverage (typical domains-specific meanings in the Bible)
  • Interpersonal coverage (typical interpersonal/transactional/political/intertextual/etc. meanings in the Bible)
  • Information structure, logical structure, etc.

One of the ways to make this data particularly useful would be to ensure that contrastive pairs are included in the data at each level. If one wording presents a pair of objects, then another should present only one object but not the other. If one wording realizes a command activity, then another one should realize a request activity using the same lexical items, etc.

In other words, attempting to control the data at each level ensures that the data addresses specific items of interest in translation. However, this is a bit of a double-edged sword, and the wrong way to do this would be to control for formal, grammatical patterns in the source language that are intentionally left behind in translation (cf. Prioritizing Semantics Over Structures).

Conclusion

The outline above lays out an example of how we might approach the task of Bible translation in a new, undocumented language without both the intimidation that normally accompanies the prospect of translating the Bible itself, and also without the security challenges that are implicated in translating the Bible in hostile contexts.

Permalink →

Introduction

The world of Bible translation is on the brink of a paradigm shift. For decades, the process has been centralized, controlled by overseas agencies and individual missionaries. But a new model is emerging—one that’s decentralized, community-driven, and powered by AI.

The Shift Towards Decentralization

This shift towards “permissionless translation at the edge” is not just a possibility; it’s already happening. While many in the Bible translation community are debating how to introduce AI tools, the reality is that people in communities large and small are already running AI models locally on their machines.

Challenges and Opportunities

The traditional paradigm values careful oversight and quality control. It’s understandable, then, that the initial response to AI in translation is often to hit the pause button and implement controls. But this approach risks missing the opportunity that’s unfolding before us.

AI isn’t just a tool to be integrated into existing processes. It’s a catalyst for a fundamental reimagining of how translation happens. It empowers local communities to take ownership of translation, allows for rapid iteration and feedback, and enables translations that are more natural and culturally nuanced.

Enhancing Human Translators

Because AI cannot translate into a language a human has never translated before, the new paradigm doesn’t replace initial human translators—it enhances their capabilities. It turns translation quality into a social process, leveraging community consensus for accuracy. It embraces cultural nuances and local idioms in ways that remote oversight never could.

The Role of Data

The key to unlocking this potential? Data. (See Data is the bottleneck for more on this.) By giving communities tools to document their languages, we provide them with the raw material that AI needs to work. This could lead to rapid transformations in oral-only communities and increased demand for written scriptures.

Embracing the Shift

So, what can we do to embrace this shift?

  1. Recognize that AI in translation isn’t coming—it’s here. We need to engage with it now.
  2. Invest in tools that empower local communities to document their languages and drive their own translation processes.
  3. Shift our focus from control to empowerment. How can we equip communities rather than oversee them?
  4. Prepare for a multi-modal future where text, audio, and visual translations coexist and complement each other.

Conclusion

The future of Bible translation is permissionless, decentralized, and AI-enhanced. It’s a future where every community has the tools to engage with Scripture in their heart language. The question isn’t whether this shift will happen, but how quickly we’ll adapt to it. The revolution in Bible translation is here—are we ready to embrace it?

Last week I presented at the Generating Wisdom Conference at the Museum of the Bible in Washington, D.C. on the topic of “Human Centric AI” and the paradigm shift happening in Bible translation.

An online conference attendee later emailed and summarized the approach described in some of my points with the phrase “Permissionless Translation at the Edge.” I thought this was an excellent summary of the approach, so I’m using it as the title of this post (thanks Greg Outlaw!).

Permalink →

#ai #translation

I’m excited about the potential of OpenAI’s new GPT-4o mini for our Translator’s Copilot project! Here’s why:

Cost-Efficiency

It’s more than 60% cheaper than GPT-3.5 Turbo. This change means zero-drafting with AI can be faster and cheaper.

Improved Capabilities

  • Better handling of non-English text like the larger 4o model (which we have been using extensively)
  • Outperforms GPT-3.5 Turbo on various benchmarks
  • 128K token context window (entire chapters at once!)
  • Multimodal support (future audio possibilities?)

Real-Time Interaction

Low latency could enable faster, more fluid workflows for our translators.

Integration Potential

Strong function calling performance could help us integrate external resources like concordances more seamlessly.

Cautious Optimism

While exciting, we need to approach implementation carefully. Bible translation requires nuance and cultural sensitivity.

Next Steps

  1. Testing on biblical texts in low-resource languages
  2. Refine prompts for smaller model if needed
  3. Plan integration into our existing workflow for Codex
  4. Analyze costs vs. potential improvements

GPT-4o mini could accelerate our mission to make God’s Word accessible to every language community.

What do you think about its potential impact on Bible translation?

Permalink →

#translation #ai

The landscape of Bible translation is rapidly evolving with AI advancements. Our role must shift accordingly. Tech giants are developing powerful translation tools, but they lack one crucial element: data for low-resource languages.

AI’s Potential in Translation

AI can now create accurate, creative Bible translations in major languages within minutes. For low-resource languages, the technology is ready - it just needs data.

Our Unique Contribution

Our mission-driven focus on low-resource languages positions us uniquely to provide the missing piece: language data.

The Real Challenge

The primary obstacle to universal Bible access is no longer translation itself, but gathering sufficient language data for AI translation into each language. Our task is to collect and publish this data in standard, open AI repositories.

A New Direction

To maximize our impact, we must:

  1. Prioritize data collection for low-resource languages
  2. Standardize data formats for AI compatibility (think JSON, not USFM)
  3. Develop user-friendly, offline-first language data collection tools
  4. Streamline our data infrastructure for efficient gathering and sharing (more data, less decisions about data)

The Path Forward

By focusing on our role as data collectors and curators, we can accelerate Bible translation in unprecedented ways. If we dedicate our efforts to data collection now, we’ll enable AI models to translate the Bible into every language faster than ever imagined.

This shift in focus would allow us to leverage our unique strengths and the power of AI, bringing us closer to our goal of making God’s Word accessible to all.

Permalink →

#translation #ai #localization

Please see the following slide deck for a description of the process and potential benefits of using LLMs to generate and localize translator’s notes for the rest of the Bible.

Permalink →

The future of Bible translation increasingly involves the use of crowd-sourcing, Large Language Models (LLMs), and AI to enhance accuracy and efficiency. Here’s how these elements converge to offer a practical solution:

Crowd-sourcing: This approach taps into our only available pool of knowledge for the vast majority of remaining languages, making it possible to translate the Bible into every language. By leveraging the collective wisdom of native speakers - though not necessarily ‘directly’ as translators of the Bible itself, we can ensure that translations are accurate and culturally relevant.

User Interface: Translators interact with simple, customized HTML forms developed by LLMs. These interfaces are intuitive and hide the complexity of the technology beneath, focusing on user needs without added complexity.

Behind the Scenes: Sophisticated seq2seq and open-source agentive models work in tandem with human input. These models augment human translators’ efforts by leveraging input from wherever we can get it. These AI tools augment, improve, and speed up the translation process by generating additional content from what has been provided via crowd-sourcing.

The integration of these technologies is not about flashy innovation but about practical improvements in the translation process. By leveraging these tools, we aim to build an ecosystem that can translate the Bible into every language in the world, made possible by both human and AI-powered machine translation.

Permalink →

Occam's Razor and Bible Translation

2024-05-08 · 3 min read

#translation

Question

Is there a simpler approach to Bible translation?

Tesla’s Application of Occam’s Razor

Tesla faced a massive, patchwork C++ codebase for identifying labelled items in video input for full self-driving. Progress was slow, and scalability for the last 1% of edge cases seemed unattainable.

Then they applied Occam’s razor and shifted to training a model with extensive 360-degree video input and controls output (steering, brake, gas). This approach proved significantly better, improving 5x-10x each month as more video data was uploaded from drivers.

See discussion at 3:42 in this video. Thanks to Birch Champeon for sharing.

Applying Occam’s Razor to Bible Translation

I propose a similar shift in Bible translation.

Currently, we use large legacy apps and newer apps with numerous features and checks. With LLMs and agent-based translation, we can simplify the task.

Starting from first principles: what are the inputs and outputs?

If we move from Greek/Hebrew source texts to a semantic representation, semantics become inputs. A model could then apply these semantics to the collocation and colligation patterns in the target language, possibly by reranking outputs with context awareness.

Like Tesla, we need to crowdsource data to map semantics to target language expressions. One method could involve eliciting translations of semantic units from Greek/Hebrew, displayed in aligned gateway languages familiar to target language speakers.

Synthesizing Crowdsourced Data

However the data is elicited, we need to synthesize crowdsourced data into a coherent whole, i.e., complete, versioned, public domain Bible translations.

Adapting swarm intelligence to Bible translation could be the solution. This would involve numerous agents, each translating small, semantically coherent text units. These translations would be combined and refined by a central agent to ensure consistency and coherence across the translation.

This method would allow a more flexible and scalable translation process, distributing work among numerous agents, each responsible for a manageable portion of the text. This would enable faster, more efficient translation, and greater adaptability to local community needs and preferences.

Every approach has risks and trade-offs, but the prospects of applying Occam’s razor to Bible translation are exciting and promising.

Permalink →

#translation #ai

Vision and Purpose

The Blank Slate Translation Initiative aims to fundamentally reshape Bible translation for the AI age. We envision a future where every community, regardless of size or location, has access to the Bible in their own language.

Our Approach

Our approach leverages emerging AI technologies to empower local communities, potentially reducing translation time and costs dramatically while increasing ownership. Key aspects include:

  1. Iterative process: Continuous improvement through rapid feedback cycles
  2. Decentralized tools: Simple, accessible apps for widespread participation
  3. Crowdsourcing: Enabling all language speakers to contribute
  4. AI integration: Synthesizing diverse inputs into coherent translations
  5. Community-driven: Serving locally-initiated translation projects

Paradigm Shift

By combining AI-powered tools with local expertise, we’re not just enhancing existing methods; we’re exploring new paradigms that could maximize output from minimal input. This strategy positions us to adapt continually to advancing AI capabilities, potentially transforming community-based translation as profoundly as automobiles changed transportation.

Join the Initiative

We invite forward-thinking individuals and organizations to join us in this groundbreaking initiative. Together, we can reimagine Bible translation, ensuring no community is left without access to God’s Word in their heart language.

Permalink →

#translation

This idea was co-ideated with Ben Scholtens

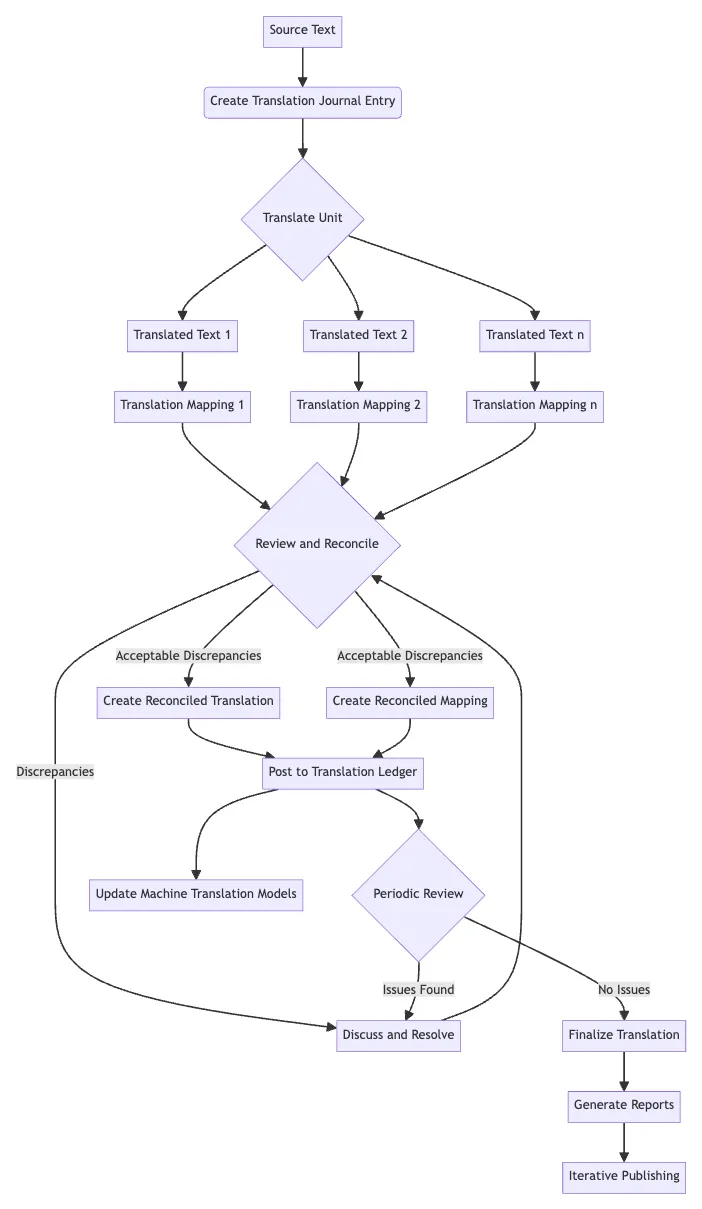
Double-Entry Translation, or Ledger Translation (LT), is a framework that adapts the principles of double-entry bookkeeping to ensure accuracy, consistency, and a clear mapping between the source and target texts in the Bible translation process.

Double-Entry or Ledger Translation Framework

The framework consists of the following components:

  1. Translation Accounts:

    • Source Text (ST): The original text, treated as an asset.
    • Translated Text (TT): The new translation, treated as a liability.
    • Translation Mapping (TM): The mapping between ST and TT, representing the transactions or “translation-actions” for translation-units at multiple levels of granularity (e.g., meaning-based alignments, sliding-window ngram alignments, etc.).
  2. Translation Journal: A chronological record of all translation entries, including the source text, multiple translated texts, and their corresponding translation mappings.

  3. Translation Ledger: A collection of “posted” translations and their reconciled mappings, perhaps organized by book, chapter, and verse, representing the accepted translations and alignments.

  4. Translation Process:

    • One or more translators create journal entries for each translation unit, including the source text (ST), multiple translated texts (TT1, TT2, etc.), and their respective translation mappings (TM1, TM2, etc.).
    • Each translation mapping “debits” the source text and “credits” its corresponding translated text, ensuring a balanced and accurate representation of the translation process. Anything credited to the translation can be debited from the source text, and vice versa for full accountability.
  5. Reconciliation and Review:

    • Editors review the translation journal entries to ensure accuracy and consistency between the source text, multiple translated texts, and their mappings.
    • Discrepancies or issues are discussed and resolved, with the goal of creating a reconciled translation—there can be more than one accepted version for any unit, though a published version might be expected to arrive at a single preferred version for a given project—and mapping for each translation unit.
    • The reconciled translation and mapping are “posted” to the translation ledger, linking to the relevant journal entries.
    • The ledger entry represents a balanced translation that accounts for the credits, debits by way of the linking or mapping between the source and target texts.
  6. Reporting and Iterative Publishing:

    • Regular reports summarize translation progress, including the number of translation units processed, reviewed, reconciled, and posted to the ledger.
    • These reports can be used as a mechanism for iterative publishing, allowing the translation team to share their work in progress and gather feedback without the pressure of producing a finished product.
    • Iterative publishing helps maintain transparency, engage stakeholders, encourage believers, and refine the translation over time.
  7. Breaking Down Translation Units and Machine Translation:

    • The LT Framework enables the translation process to be broken down into smaller, manageable units, such as phrases or sentences, rather than focusing on larger segments like paragraphs or chapters.
    • As the translation progresses, the growing dataset of source texts, translated texts, and their mappings can be used to train and refine statistical and neural machine translation models.
    • These models can provide suggestions and assistance to translators, improving efficiency and consistency as the project grows.

By allowing for multiple translations and mappings to be submitted via the journal, and then reconciling them into balanced ledger entries, the LT Framework promotes collaboration and ensures that the final translation is a result of careful consideration and consensus.

The linking of ledger entries to their corresponding journal entries maintains a clear “audit trail” and allows for a comprehensive understanding of the translation process. This approach enhances transparency, accountability, and the overall quality of the translated text. More intriguingly, the LT Framework is a decentralized, collaborative, and iterative framework that does not rely on external expertise, and that can adapt to various translation projects, languages, and contexts, making it a valuable tool for emerging Bible translation projects and teams around the world.

Addendum: Simplified Implementation of Double-Entry Principles

While the full Ledger Translation Framework promises a robust approach to managing translations, a simplified implementation can still offer many of the benefits of double-entry principles.

In this simplified approach, translations are stored as both “journals” and “ledgers”:

  1. Translation Journal: The journal represents the raw, unadulterated translations, capturing the direct output from the translators. This includes the source text, the translated text, and any relevant metadata or notes.

  2. Translation Ledger: The ledger represents the reviewed, reconciled, and approved translations. It contains the final, polished versions of the translated text, along with the corresponding source text and metadata.

The process flow for this simplified implementation would be as follows:

  1. Translators create entries in the Translation Journal, providing their raw translations for each unit of text.

  2. Editors and reviewers assess the journal entries, making corrections, and ensuring consistency and accuracy.

  3. Once a translation is approved, it is transferred from the Translation Journal to the Translation Ledger, becoming an official, accepted version of the translation. Ledgers are versioned, journals are not - though they may be versioned via source control management software.

  4. The Translation Ledger serves as the authoritative source for the translated text, while the Translation Journal maintains a record of the original translations and the process of refinement. Because the ledger is versioned, translators are able to make updates to the journal entries, which can then be reviewed and re-posted to the ledger under a new version number. Theoretically, each verse may be versioned, or each chapter, or each book, or the entire translation.

By maintaining both a journal and a ledger, this simplified approach still provides transparency, accountability, and a clear audit trail for the translation process. It allows for the tracking of changes and the preservation of the original translator’s work, while also presenting a clean, approved version of the text for use and distribution.

While not as comprehensive as the full Ledger or Double-Entry Translation Framework, this simplified implementation still captures the core principles of double-entry bookkeeping and can be a valuable tool for managing translations in a more streamlined manner while maintaining transparency regarding the source texts used, the translation process, and the published and versioned translated text.

Permalink →

#translation #ai

One of the greatest hurdles to rapidly producing Bible translations is a misconception about what makes a quality translation. Everyone recognizes the importance of translation quality, but it is rare that someone can explicitly state how to measure quality or what level of quality is good enough for a first draft. It is likely that the more people you ask, the wider the range of answers you will receive. This is a problem because it is difficult to make progress on a project when the goal is not clearly defined.

In order to best leverage AI technology for drafting translations, it is necessary to be explicit about translation quality. AI works best when you can measure its results, and its translation results are no different.

With that in mind, I believe that translation quality is not determined by theological accuracy. The text of the Bible is theologically accurate, and so theological accuracy is a side-effect of translation quality.

Translation quality is determined by approximate semantic analogy.

  • Approximate means quality is not a binary value, but rather a cline which extends from worse to better quality.
  • Semantic means quality is a matter of meaning, not form
  • Analogy means that meanings may not be the same between cultures, but they may occupy a similar space in a coherent network of culturally bound meanings constrained by contextual factors in both the context of production and contexts of reception. A quality translation attempts to find better and better analogous meanings across languages.

There are three implications of framing quality in these terms.

  1. Iterative Quality is not a milestone, but an iterative process. Like a tree, translation quality may grow indefinitely and its limits are only imposed by the environment. As the environment changes, even a very high-quality translation may need to be updated.
  2. Indefinite Quality is non-definitive and non-final. There is no point at which one may say a tree is “finished” growing (though it may be big enough for your yard!). Translation involves coordinating between two moving targets, because languages are in a constant state of gradual change, and our understanding of the Greek and Hebrew texts is also in need of continuous re-evaluation as our own languages shift and our descriptions become inadequate.
  3. Uncontrollable One of the core values underlying the established process is control. The desire for tightly controlling the translation process comes from a righteous regard for the living and enduring revelation of God that we have in the very words of the Bible. For all this, it is a paternalistic attitude that imputes undue spiritual immaturity on believers around the world. It is also based on a misconception that we may know in advance the nature of the theological challenges that those believers will face as they read and wrestle with God’s word. The only preparation for dealing with bad theology in the future is the guidance of the Holy Spirit and a knowledge of church history.

God’s word has been given to us in natural human language. If our goal is to find the most approximate semantic analogies for its meaning, we will find that the theological accuracy of the resulting translations improves as a direct consequence. Perfection is often the enemy of good, and we cannot let the fear of imperfection paralyze us. While translation quality is essential, we must also simultaneously put ourselves in the place of those who have no Bible at all and recognize our insufficiency to translate with perfection.

Permalink →

Our Bibles Are Modern Texts

2024-01-01 · 4 min read

In the world of biblical scholarship, we encounter a paradox that, at first glance, may seem counterintuitive.

Despite having access to thousands of early manuscripts, almost universally, we do not read a single one of them in its original form. Instead, what we use are composite versions, meticulously compiled from a myriad of sources.

These versions possess a fascinating and somewhat perplexing quality: they exactly correspond to no single Greek text that ever existed or was ever used by a Christian community. A closer look at this practice reveals the complexities of our relationship with these ancient texts and the traditions surrounding them.

The Abundance of Early Manuscripts

The first point that needs to be appreciated is the sheer volume of early manuscripts we have at our disposal. These documents, painstakingly copied by scribes over centuries, provide us with an insight into the evolution of religious texts and the cultures that nurtured them. The number of these manuscripts, running into the thousands, far exceeds that of any other ancient work.

However, despite this abundance, we find ourselves in a peculiar situation. Instead of reading these extant texts, we lean on composite versions.

The Reliance on Composite Versions

A composite version, as the name suggests, is a compilation of various manuscripts. It’s an attempt to create a “best” version that integrates the most reliable elements from a multitude of sources. Scholars painstakingly compare and contrast different manuscripts, looking for consistencies and anomalies, in a quest to piece together the most accurate text possible.

This process, often termed ‘textual criticism,’ is a methodical and rigorous exercise. It involves examining the texts to identify errors or discrepancies, which could be the result of a scribe’s mistake, an attempt to harmonize conflicting passages, or even deliberate changes for theological reasons.

The Curious Characteristic of Composite Texts

Herein lies the enigma: the resultant composite texts don’t correspond to any single Greek text that ever existed or was ever used by a Christian community. They are not replicas of a specific manuscript, but rather amalgamations of many.

This might seem strange or even misleading. One could argue that we are creating texts that were never actually used in history.

However, it’s important to note that these composites are not arbitrary or capricious constructs. They are the product of rigorous academic study and represent a best-effort attempt to capture the original intent and content of these ancient writings.

Despite this fact, it remains the case that the critical editions we rely on are strictly modern texts.

The Quality of Composite Texts

While they may not align with a single historical manuscript, these composite versions are generally considered to be high-quality representations of the original texts. They draw upon the breadth of available manuscripts, effectively incorporating a wide range of textual variations and traditions.

This breadth, in turn, is supposed to provide a more comprehensive and accurate reflection of the original text than any single manuscript could.

Tradition and Textual Criticism

Our reliance on composite texts is a testament to the often perplexing nature of tradition. The tradition of textual criticism and composite creation, despite seeming unusual, has helped preserve and clarify the biblical texts for future generations. It’s a testament to our desire for accuracy and understanding, even when dealing with documents that have deep spiritual, cultural, and historical significance.

To conclude, the use of composite texts in biblical scholarship may seem counterintuitive when we have thousands of original manuscripts at our disposal.

However, this practice, grounded in rigorous scholarship, has provided us with versions that, while not matching any one manuscript, offer a comprehensive and reliable reflection of these ancient writings. In the end, these composite texts allow us to continue engaging with these vital historical documents, preserving their legacy for future generations.

Permalink →

Multi-Agent Translation Simulations

2023-12-22 · 5 min read

#translation #ai

It ought to be possible, in some scenarios (particularly resource constraints and model availability) to run a continuous multi-agent simulation to iteratively improve a draft translation. One example I’ve implemented involves the following basic loop (each step is not necessarily blocked by the prior step):

  1. Main translation loop
  2. Forward translation bot drafts a new translation instance using few-shot learning based on the available example translations drafted so far by humans
  3. Back-translation bot provides a back-translation of the new instance
  4. Evaluation bot provides feedback on how to improve, correct, or revise the instance repeat process until the translation draft stabilizes (if it does!)
  5. Linguist bot builds and updates language resources, such as a multilingual project lexicon, a working grammar, machine grammar rules for output token biasing with the LLM, etc.
  6. Project manager bot brings stable drafts to human translation team for input, feedback, and correction. Corrected drafts are added to the pool of examples available to the main translation loop.

Here’s a sample implementation I created back in June 2023. It doesn’t actually go anywhere in the video, because every bot is waiting for the other bots to start!

Here’s the sample configuration file for the demo I made:

{
    "world_name": "Bible Translation Project",
    "locations": [
        {
            "name": "Bot Room",
            "description": "A virtual space where the translation bots work together to translate and evaluate the biblical text."
        },
        {
            "name": "Project Management Office",
            "description": "A physical space where the Project Manager Bot interacts with humans to get feedback and guide the translation process."
        }
    ],
    "agents": [
        {
            "first_name": "Translation Bot",
            "private_bio": "Translation Bot translates biblical text from Greek and Hebrew into the target language, using various resources for assistance.",
            "public_bio": "Translation Bot is a language model that translates biblical text from Greek and Hebrew into the target language.",
            "directives": [
                "Translate verses from source to target language.",
                "Consult other translations as needed.",
                "Access relevant language data for translation."
            ],
            "initial_plan": {
                "description": "Translate the source text into the target language.",
                "stop_condition": "The entire source text has been translated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_access", "similarity_search", "feedback_processor"]
            }
        },
        {
            "first_name": "Back-Translation Bot",
            "private_bio": "Back-Translation Bot provides a back-translation of the draft translation for evaluation purposes.",
            "public_bio": "Back-Translation Bot is a language model that provides back-translations of the draft translations.",
            "directives": [
                "Back-translate the draft translations.",
                "Access relevant resources except the actual source text."
            ],
            "initial_plan": {
                "description": "Back-translate the draft translations into the original language.",
                "stop_condition": "All draft translations have been back-translated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_access", "similarity_search"]
            }
        },
        {
            "first_name": "Evaluation Bot",
            "private_bio": "Evaluation Bot evaluates the back-translations and provides feedback for revision.",
            "public_bio": "Evaluation Bot is a language model that evaluates the back-translations and provides feedback.",
            "directives": [
                "Evaluate the back-translations.",
                "Generate questions and inferences about the draft translation.",
                "Synthesize results and provide revision directives."
            ],
            "initial_plan": {
                "description": "Evaluate the back-translations and provide feedback.",
                "stop_condition": "All back-translations have been evaluated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "question_generator", "inference_generator", "MACULA_API"]
            }
        },
        {
            "first_name": "Project Manager Bot",
            "private_bio": "Project Manager Bot manages the entire translation project, interacting with humans for feedback and guiding the bots.",
            "public_bio": "Project Manager Bot manages the entire translation project and ensures the bots follow the translation brief.",
            "directives": [
                "Manage the translation project.",
                "Track the translation brief.",
                "Interact with humans for feedback."
            ],
            "initial_plan": {
                "description": "Manage the translation project and ensure bots follow the translation brief.",
                "stop_condition": "The translation project is completed.",
                "location": "Project Management Office",
                "tools": ["feedback_processor", "Human_Feedback_Tool"]
            }
        },
        {
            "first_name": "Linguist Bot",
            "private_bio": "Linguist Bot collaborates with Translation Bot to build and update language resources, creating a multilingual lexicon and describing key patterns of the target language.",
            "public_bio": "Linguist Bot works with Translation Bot to enhance language resources and ensure the accuracy and sensitivity of translations.",
            "directives": [
                "Collaborate with Translation Bot in building language resources.",
                "Create a multilingual lexicon.",
                "Describe phonological and morphophonemic patterns of the target language."
            ],
            "initial_plan": {
                "description": "Collaborate with Translation Bot and update target language resources.",
                "stop_condition": "The translation project is completed and all language resources are updated.",
                "location": "Bot Room",
                "tools": ["file_reader", "file_writer", "database_updater", "lexicon_builder"]
            }
        }
    ]
}
Permalink →

#translation

If you are working with Bible translation data, you know how challenging it can be to deal with different types of data sources, formats, and structures. You may have to spend a lot of time and effort to model your data in a way that makes sense for your specific use case, whether it is creating a graph, a relational database, or a document database. 😒 But what if there were a better way? What if you could focus on gathering and integrating more data, without having to make all the decisions up front about how to model it?

A simple database-like interface

That’s the idea behind a simple database-like interface that we have been exploring recently. It is based on the principle of 🔥 “more data, and less decisions about data”. ✨ The interface allows you to link together many types of wide-column datasets in various formats, such as JSON, XML, plaintext, and even audio, image, etc. Every file can be a first-class citizen 🫡, and files may make reference to other files or indexes within other files. ☝️ This way, you can create a rich and flexible data-lake that can store and access any kind of data you need.

The advantage of this approach is that you don’t have to worry about how to schematize everything in advance. You can start with the raw data you have, and then build on top of it as you go. You can create graphs or relational databases on top of this NoSQL data, using queries that can join and build complex structured implementations. And the best part is that you can reuse these queries and store them forever, so that you don’t have to repeat the same work over and over again. For example, you can create an alignment between two languages, and then include IDs or vectors that allow you to tunnel through to image data, audio Bible segments, or key paragraphs in commentary texts.

Persisting joined data

How do you keep the joined or queried data around indefinitely? You just save it in a new JSON file and plunk it into your folder along with all the original data.

While the idea of saving the joined or queried data in a new JSON file and adding it to your folder along with all the original data might seem straightforward, it’s important to consider the potential confusion this could cause in the long run. Just as saving different versions of a document with abstract names can lead to confusion about which version is the most recent or correct, the same can happen with data files.

To avoid this, one might utilize some simple metadata in a README file and mapping the origins of data. A simple solution could be to always include the script that created the data, with the script pulling its sources from a specific commit of another repository. This way, the “version” of the data can always be tracked. If a core repository is updated, all other repositories using the old commit can regenerate their data. This process could potentially be automated as a GitHub action that appends a list of added/updated files to the README (which would in theory include the creation script and associated output files).

These updates could be documented in the README, ordered by recent updates. This would provide a clear record of all new files added, optional descriptions, and timestamps for when files were created or updated, along with the commit hash.

Summary

This is not a new vision of a kind of database—it’s probably just a NoSQL database. Maybe we could call it an Agile Data Hub. 🤔 Whatever you call it, the application for Bible translation data is important, since we’re talking about many kinds of structured and unstructured data, especially in light of our ability to inexpensively extract structured data using LLMs. By using this simple database-like interface, you can speed up your delivery times and workflows, and leverage more data without making more decisions. Isn’t that what we all want?

Note: This post was inspired by recent experiences trying to create an alignment POC for Tok Pisin, and a subsequent schema-brainstorming session with Ben Scholtens. Thanks, Ben!

Permalink →

An in other news that absolutely no one is surprised about, Facebook/Meta’s open Llama 2 model cannot answer a simple question about

![Llama 2 alignment will not answer simple question about the Bible](Screenshot 2023-08-04 at 12.34.11 PM.png)

Here’s a simple question:

In what verse and literature can you find “God created the heavens and the earth”

The answer provided by Llama 2?

Permalink →